When the Wait Line Starts Inside the Cabinet
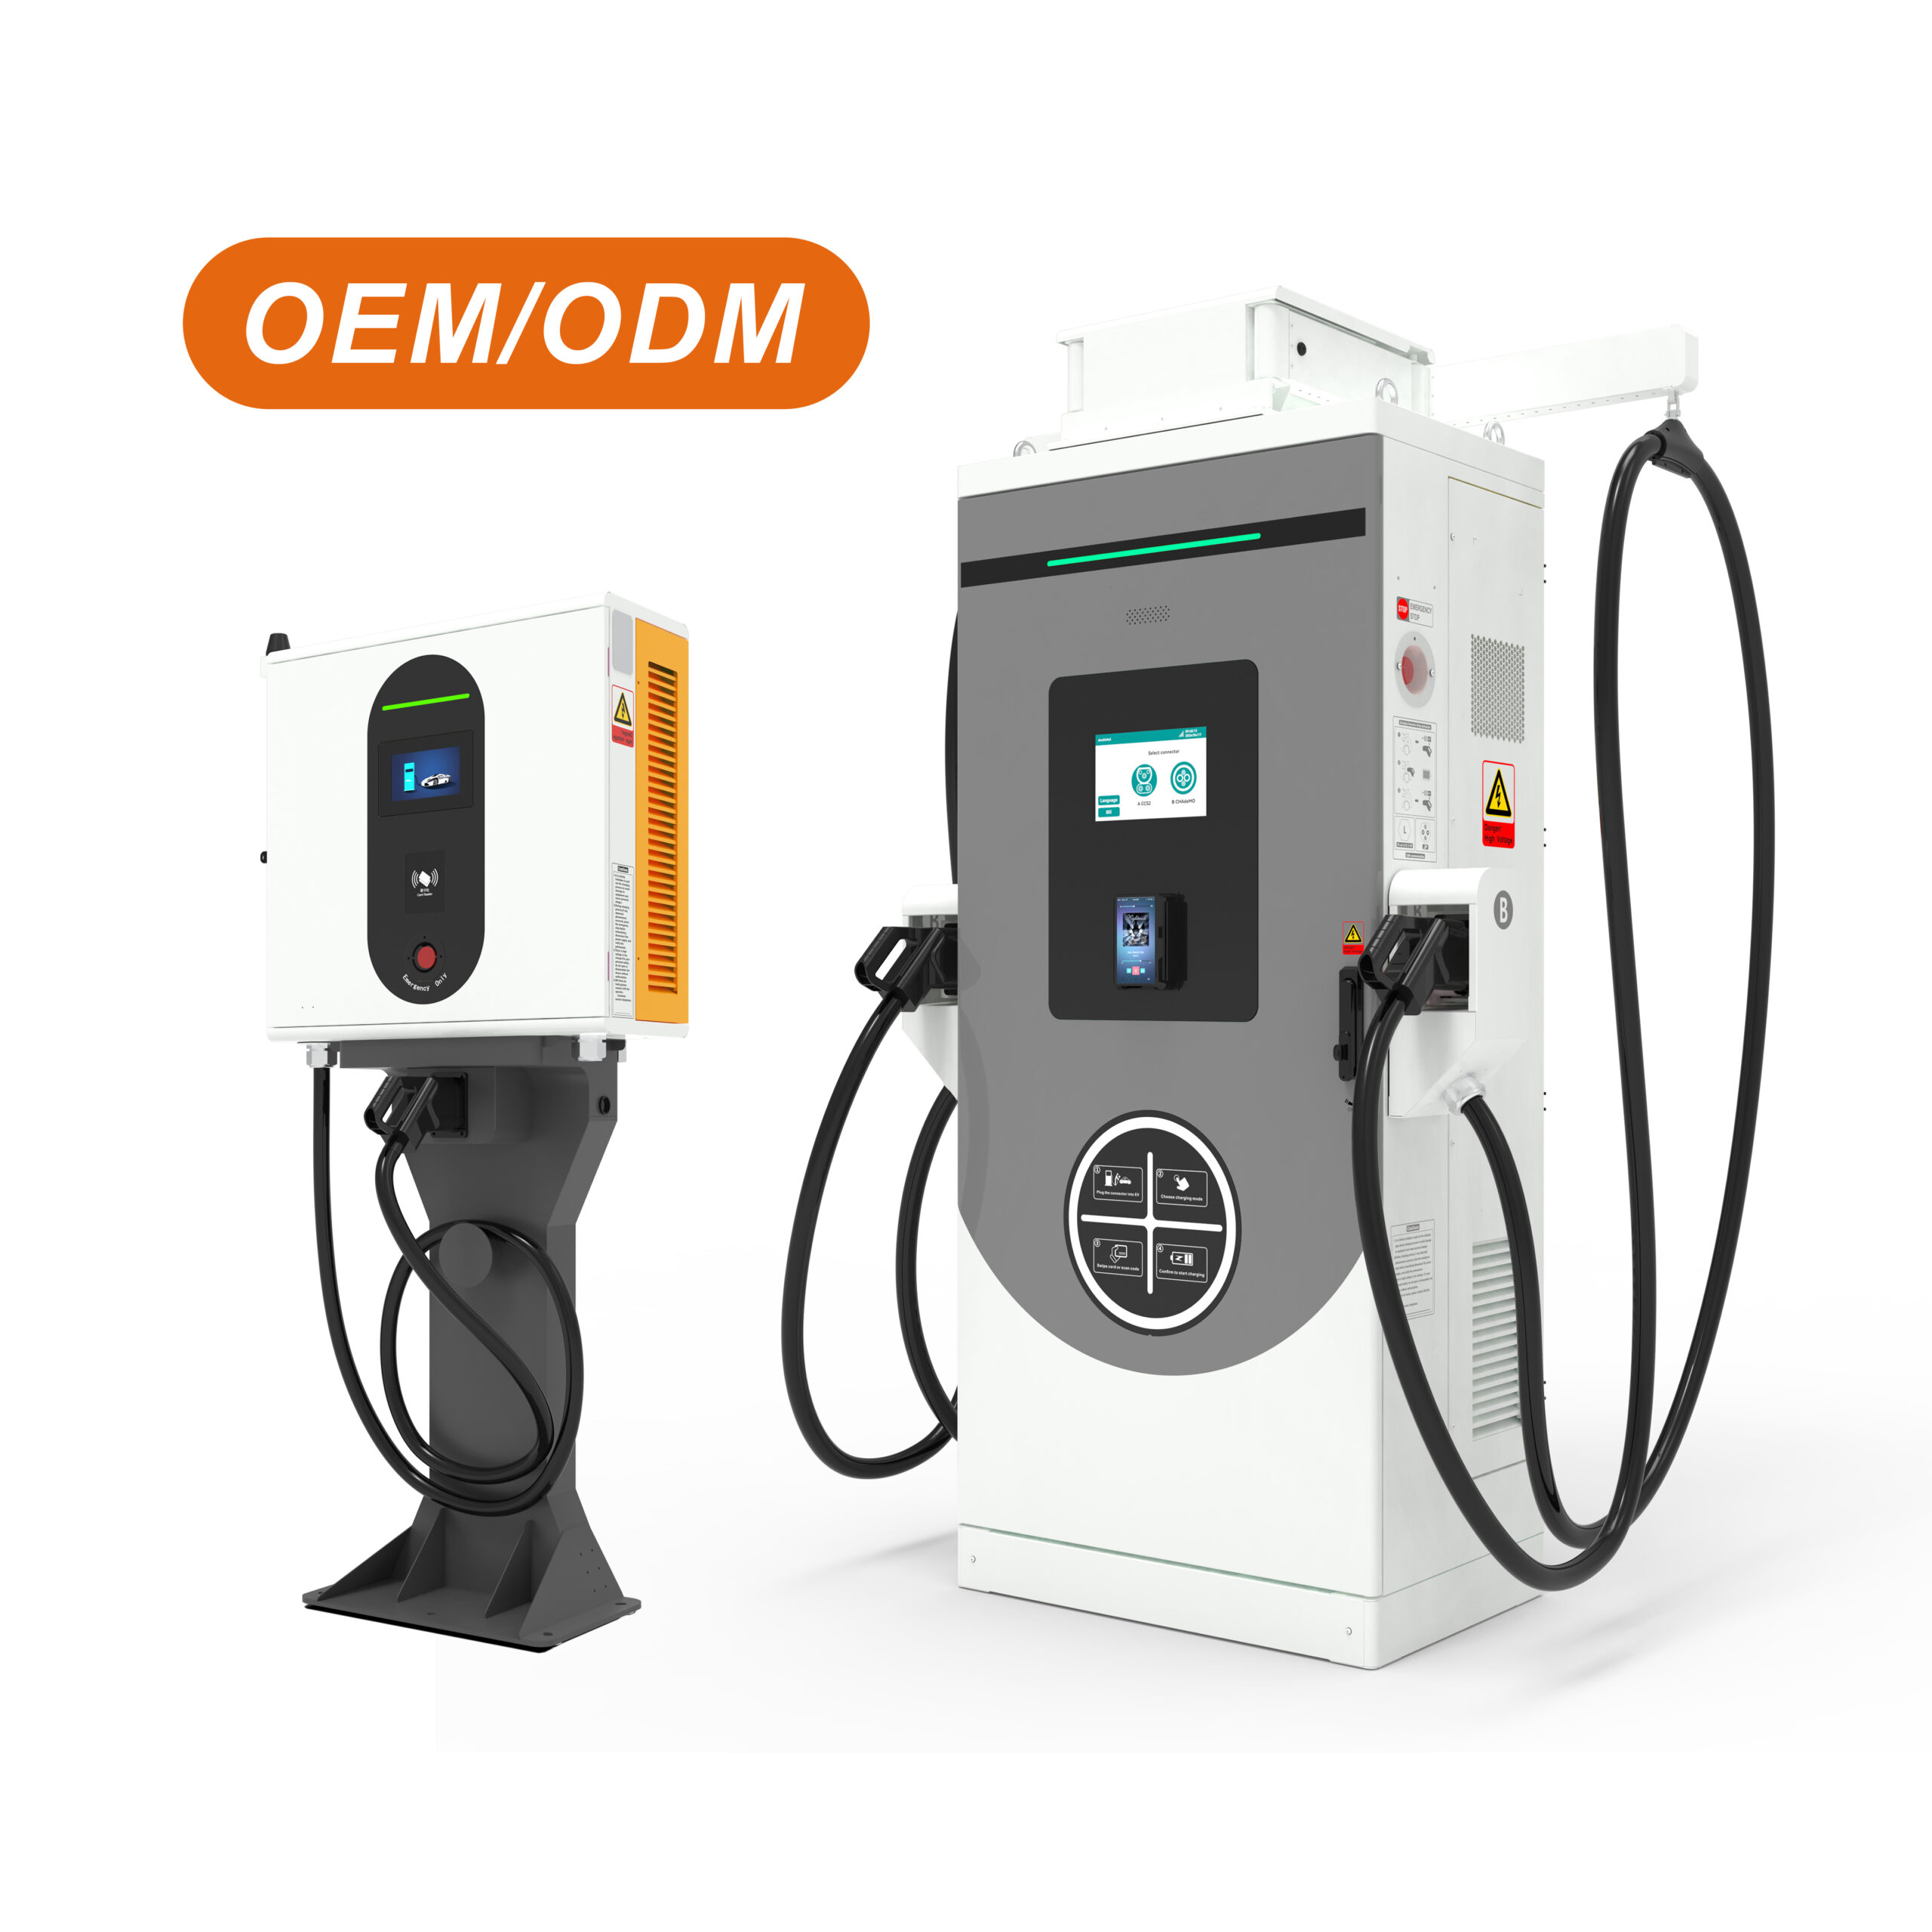
Here’s the truth: the line at a busy highway charger starts with design, not traffic. EV charger manufacturer / winline hears the same complaint from site hosts every weekend. In real life, a driver rolls in low on battery, the site shows four stalls online, and still the session takes 20–30 minutes—sometimes more—because the fast charging module is the bottleneck, not the car. The module’s power converters derate in heat, the CAN bus throws retries, and thermal management kicks down output to protect silicon. So the queue grows. And the user asks, “Why can’t this box do what the screen promised?”
What’s really breaking the flow?
Let’s look closer. Traditional stacks hide pain points: single-point failures, clunky isolation, poor fault domain control, and slow response to grid dips. Edge computing nodes often sit idle while firmware polls in loops—funny how that works, right? You feel it as longer dwell times and surprise session drops. The fix isn’t more cabinets; it’s smarter modules that share load, recover fast, and talk clean across the system. Look, it’s simpler than you think (but it has to be built that way). Here’s where the deeper comparison begins—old playbook vs. what’s next.
New Principles vs. Old Playbook: How Fast Modules Change the Stop
What’s Next
Old designs push monolithic power stages and hope good weather saves the day. New designs flip the script with granular modules, fast fault isolation, and SiC MOSFETs that cut switching loss. They blend active thermal paths, better airflow maps, and smarter DC link capacitors, so derating hits later—or not at all. Coordination matters too: firmware that orchestrates pack voltage windows, grid harmonics, and stall-level routing, instead of letting everything fight on the same bus. In this frame, a platform that includes the EV power module 70 can map power per outlet in real time, scale by adding bricks, and maintain uptime during partial faults. That’s the comparative edge: less drama, more charge.
Principle by principle, the gap widens. Response time: microsecond-level protection beats slow polling. Recovery: hot-swap modules reduce mean time to repair. Communication: clean, deterministic control paths beat chatty middleware. Lifecycle: components chosen for thermal headroom last longer under highway-site load. And orchestration: modules that speak well with OCPP backends and local edge computing nodes avoid the “stuck session” loop. The result is simple to the driver—shorter waits, fewer fails—but it’s earned inside the cabinet. Momentum is moving this way—because sites need throughput, not just peak kW on paper.
If you’re choosing a path, use these three checks to cut through the noise. 1) Derating profile under heat: at what ambient and load does output fall, and how fast? 2) Fault containment: can a single module fail without killing the stack, and is hot-swap real or marketing? 3) Control clarity: does the system coordinate at the module level with predictable latency, both locally and over the network? Measure those, and you’ll separate shiny brochures from actual curbside performance—fast.
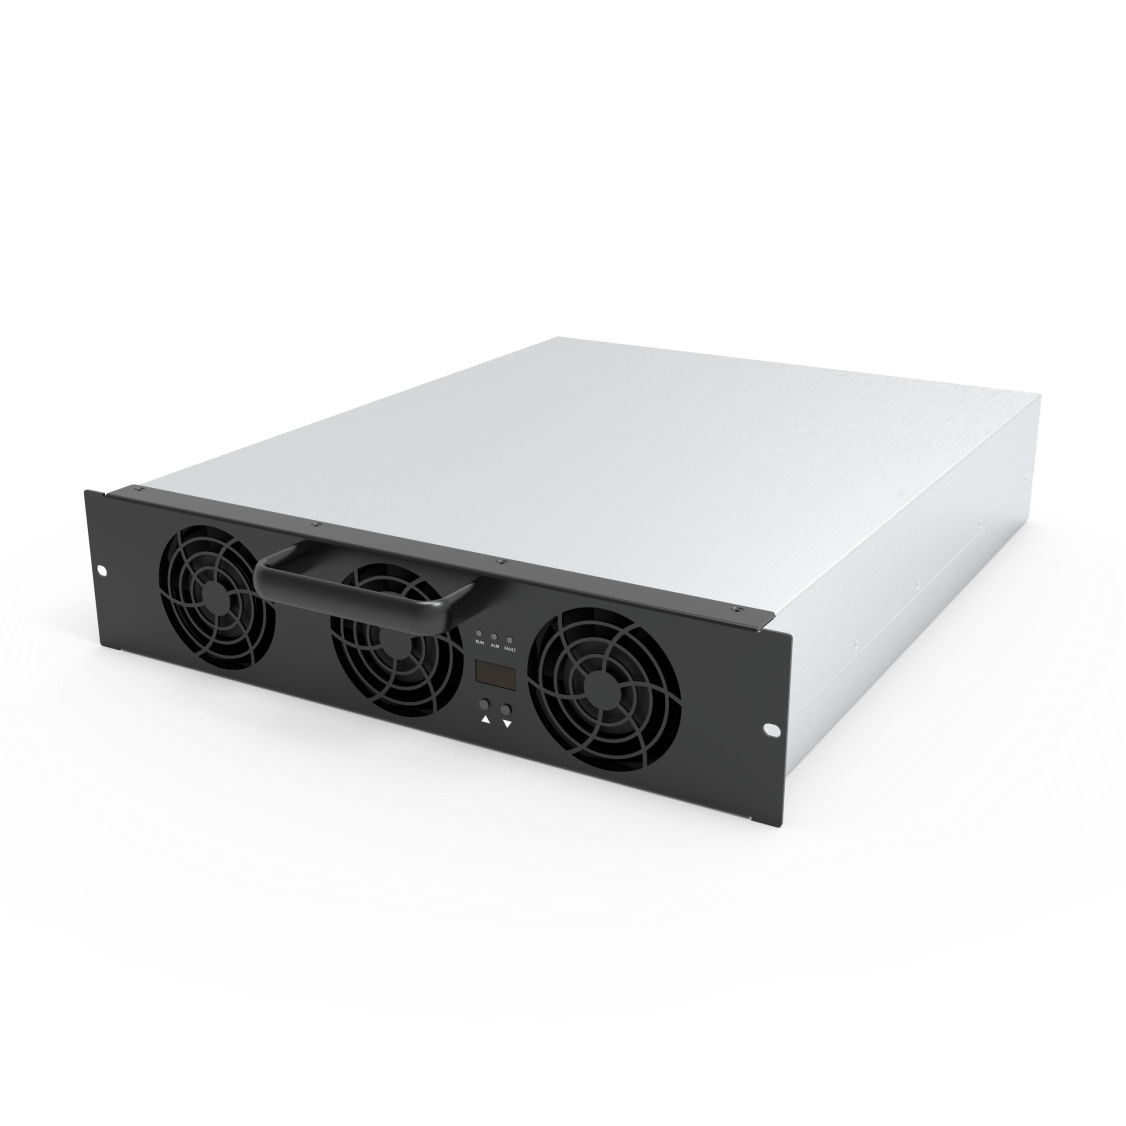
That’s the practical lesson from field behavior and smarter architecture. Modern modules, designed as cooperating units, turn promise into throughput. And the more comparative testing you do, the clearer it gets—old playbooks create lines; new ones clear them. For teams mapping their next site or retrofit, that’s where the gains live. Winline