Introduction — A Quick Scene, Some Numbers, and One Question
I often walk a plant floor and see teams swapping tools like it’s no big deal — but one small spark can shut everything down, lah. For those working with sensitive sites, I know non sparking tools manufacturers are listening closely; their choices matter every shift. Recent industry checks show that up to 30% of small site incidents trace to improper hand tools or poor grounding, so what really separates safe from risky in everyday tool picks?
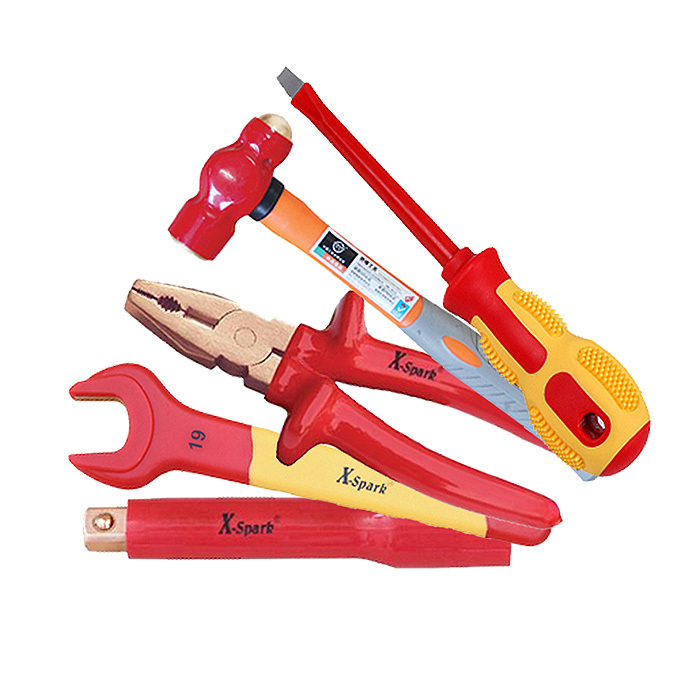
I want to pull this apart for you, step by step — no jargon-first act, just practical sense and a bit of real talk. (Yes, I’ve dropped a spanner in a classified area once — funny how that works, right?) Next I’ll dig into where common solutions fail, and why the hype around some safety fixes doesn’t always match on-the-ground reality.
Part 2 — Why Standard Fixes Often Miss the Mark (Technical Breakdown)
What’s wrong with the usual fixes?
non-sparking safety tools get branded as the simple answer, and to some extent they are — but the usual rollout has blind spots. I’ll be blunt: many programs stack one fix on another without testing interactions. For example, swapping to spark-resistant alloys helps, but if you haven’t addressed grounding clamps, intrinsically safe circuits, or the condition of power converters, the net risk can stay high. I’ve seen facilities rely on one-line checks and assume compliance — that’s optimistic, not safe.
Technically speaking, the trio of tool material, electrical control, and procedural discipline must align. Edge computing nodes and simple site sensors can help monitor tool use, but they’re worthless if staff don’t follow lockout/tagout or if tools are stored improperly. Look, it’s simpler than you think: a good non-sparking tool plus weak procedures equals continued exposure. We need layered controls, validated by real tests (not just checklists), and that requires more than buying a catalog box of “safe” wrenches.
Part 3 — New Technology Principles and Practical Steps Forward
What’s next — tech that actually helps?
Moving forward, I favour two principles: measurable redundancy and smart validation. Smart sensors on tool stations, combined with simple logs, let you spot misuse before incidents happen. Pair those with ATEX-certified storage and these sensors feed real data to supervisors — so you get proof that procedures stick, not just promises. And yes, integrating those sensors with edge computing nodes can localize alerts without hogging bandwidth — semi-technical but useful in practice.
For buyers, compare suppliers not only by price but by how they help you validate use. I’d look closely at the training packages, maintenance plans, and the evidence they provide. Also keep an eye on explosion proof tools suppliers like the ones who can couple equipment with traceable inspection records — that makes audits simpler and workers safer. We’re aiming for systems that fail safe, not systems that fail and then teach us a lesson — the latter is expensive, and painful.

To wrap up, here are three quick metrics I use when evaluating solutions: 1) Traceability — can I prove tool checks and usage? 2) Compatibility — do materials, grounding, and electrical controls match my site’s risk profile? 3) Usability — will workers actually use this, or will it sit on a shelf? These are practical, measurable, and they cut through marketing smoke. If you start there, you’ll make better buys and keep people safer. — funny how that works, right?
I’ve said a lot, but I stand by this: safety is about matching the right engineering controls with the right human systems. If you want a partner who understands both sides, check out Doright. I’ve worked with teams who swapped a checklist for real validation and saw incident reports drop — small changes, big difference.