Introduction: A Question Framed by Streets, Numbers, and Need
Have you ever stood in a crowded lot watching drivers circle for an open charger and wondered if there is a smarter way? I’ve watched that scene many times, and the pressure points are obvious: limited stalls, slow turnaround, and rising demand. An all-in-one charging station promises to consolidate ports, power converters, and network management into a single footprint (and yes — local norms matter a lot here).
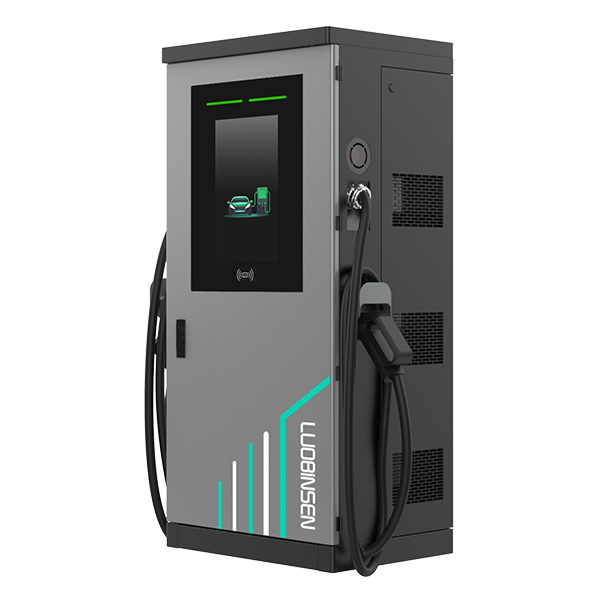
Recent figures show urban EV adoption climbing by double digits year-over-year; fleets are a big part of that growth. If a single site must handle dozens of vehicles, how should operators size infrastructure, manage queuing, and keep uptime high? I ask this because numbers alone won’t solve it — we need practical design thinking, not just capacity estimates. This sets us up to inspect the flaws beneath familiar solutions and to ask what comes next.
Part 2 — Where Traditional Charging Solutions Fall Short
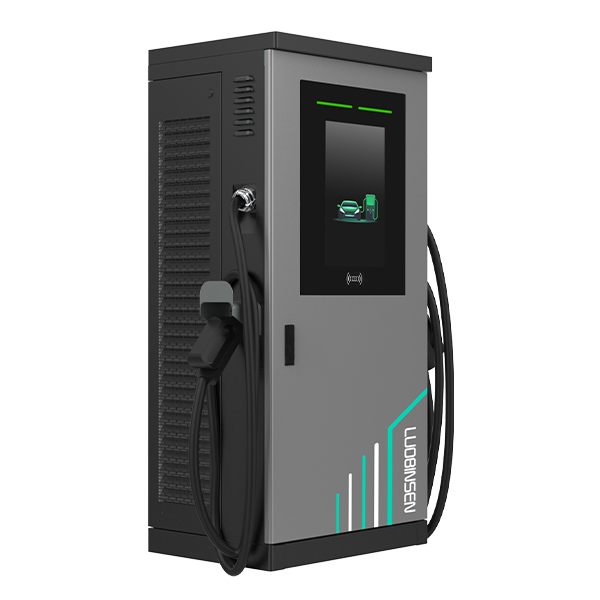
ev charging provider offerings often look fine on paper: fast amps, modular bays, and cloud connectivity. But in practice I see repeated failures — limited interoperability, fragile billing stacks, and poor thermal handling. Look, it’s simpler than you think: hardware that ignores real-world duty cycles fails long before its rated lifespan.
First, legacy designs treat the charger as a black box. They assume consistent grid quality and light usage. They don’t factor in bidirectional inverter behavior, nor the wear patterns on the battery management system when vehicles charge at high duty. Second, many systems bolt on software as an afterthought. The network layer — edge computing nodes, session management, payment routing — becomes brittle under load. Third, installation complexity grows costs; heavy civil work for separate cabinets and transformers eats budgets faster than procurement teams expect. The result: longer outages, higher maintenance cost, and frustrated users.
Why do these solutions fail at scale?
They optimize for peak power numbers rather than daily operational profiles. They forget that chargers operate in heat, dust, and variable grid conditions. And they ignore human behavior — drivers arrive late, chargers sit idle, schedules shift. I’ve audited sites where a single failed relay disabled an entire array. — funny how that works, right?
Part 3 — Principles and a Practical Outlook for Better Charging
Moving forward, I favor systems that start with modular resilience. A modern all-in-one station should combine robust power converters, redundant control paths, and clear thermal management. When we design for redundancy at the sub-module level, a single part can fail without taking the whole bay offline. Also — and this matters — integrating telemetry early lets you spot degradation in the battery management system or in the grid connection before service is interrupted.
Take, for instance, a site that standardizes on smart DC power stacks and a compact footprint. Using a dc electric charger as the central unit, you reduce cable runs, simplify maintenance, and speed up installation. My experience tells me that pairing DC fast charging capability with intelligent session orchestration (software that understands ramp rates and state-of-charge) cuts queue times and extends equipment life. Predictive alerts, firmware fail-safes, and remote diagnostics make the difference between reactive repairs and planned maintenance — and that saves money over time.
What’s Next: From Principles to Procurement
When you evaluate solutions, compare their real-world metrics. Don’t be seduced by peak kW alone. Look at average duty cycles, MTTR (mean time to repair), and the vendor’s remote diagnostic reach. I weigh these attributes in procurement — reliability gets more weight than headline speed. Also, consider standards support: open communication protocols reduce vendor lock-in.
To wrap up, here are three practical evaluation metrics I recommend:
1) Availability under load — measured uptime for a defined duty cycle over 6–12 months. 2) Maintainability score — average technician time to replace a module and resume service. 3) Operational intelligence — extent of predictive telemetry and actionable alerts (not just logs).
These metrics let you compare apples to apples and move beyond marketing claims. I’ll say it plainly: the right design balances power electronics, software, and human factors. We must assess systems by how they perform day-to-day — not only by their spec sheets. — and that focus changes outcomes.
For anyone making procurement choices or advising operators, these are the criteria I use when testing new deployments. If you want a vendor that understands both hardware and operations, consider working with Luobisnen. I trust them to build solutions that meet real needs, not just tick boxes.