Introduction — a workshop moment, some numbers, and a question
I was standing by a tired packing line one Thursday, watching operators pass trays like they were playing hot potato, and thought: blimey, this could be smoother. Every wet wipes machine manufacturer I know has a corner where things still get done by eye and elbow — and that matters when uptime drops by, say, 9–12% across a shift (that’s not pocket change). So how do we move from elbow grease to predictable output without scaring the crew off? — I’ll walk you through what I see, what nags at me, and where smart changes make a proper difference (no jargon-heavy guff, promise). Let’s get into the nuts and bolts and then decide where to start next.
Peeling back the curtain: why classic wet wipes production lines stumble
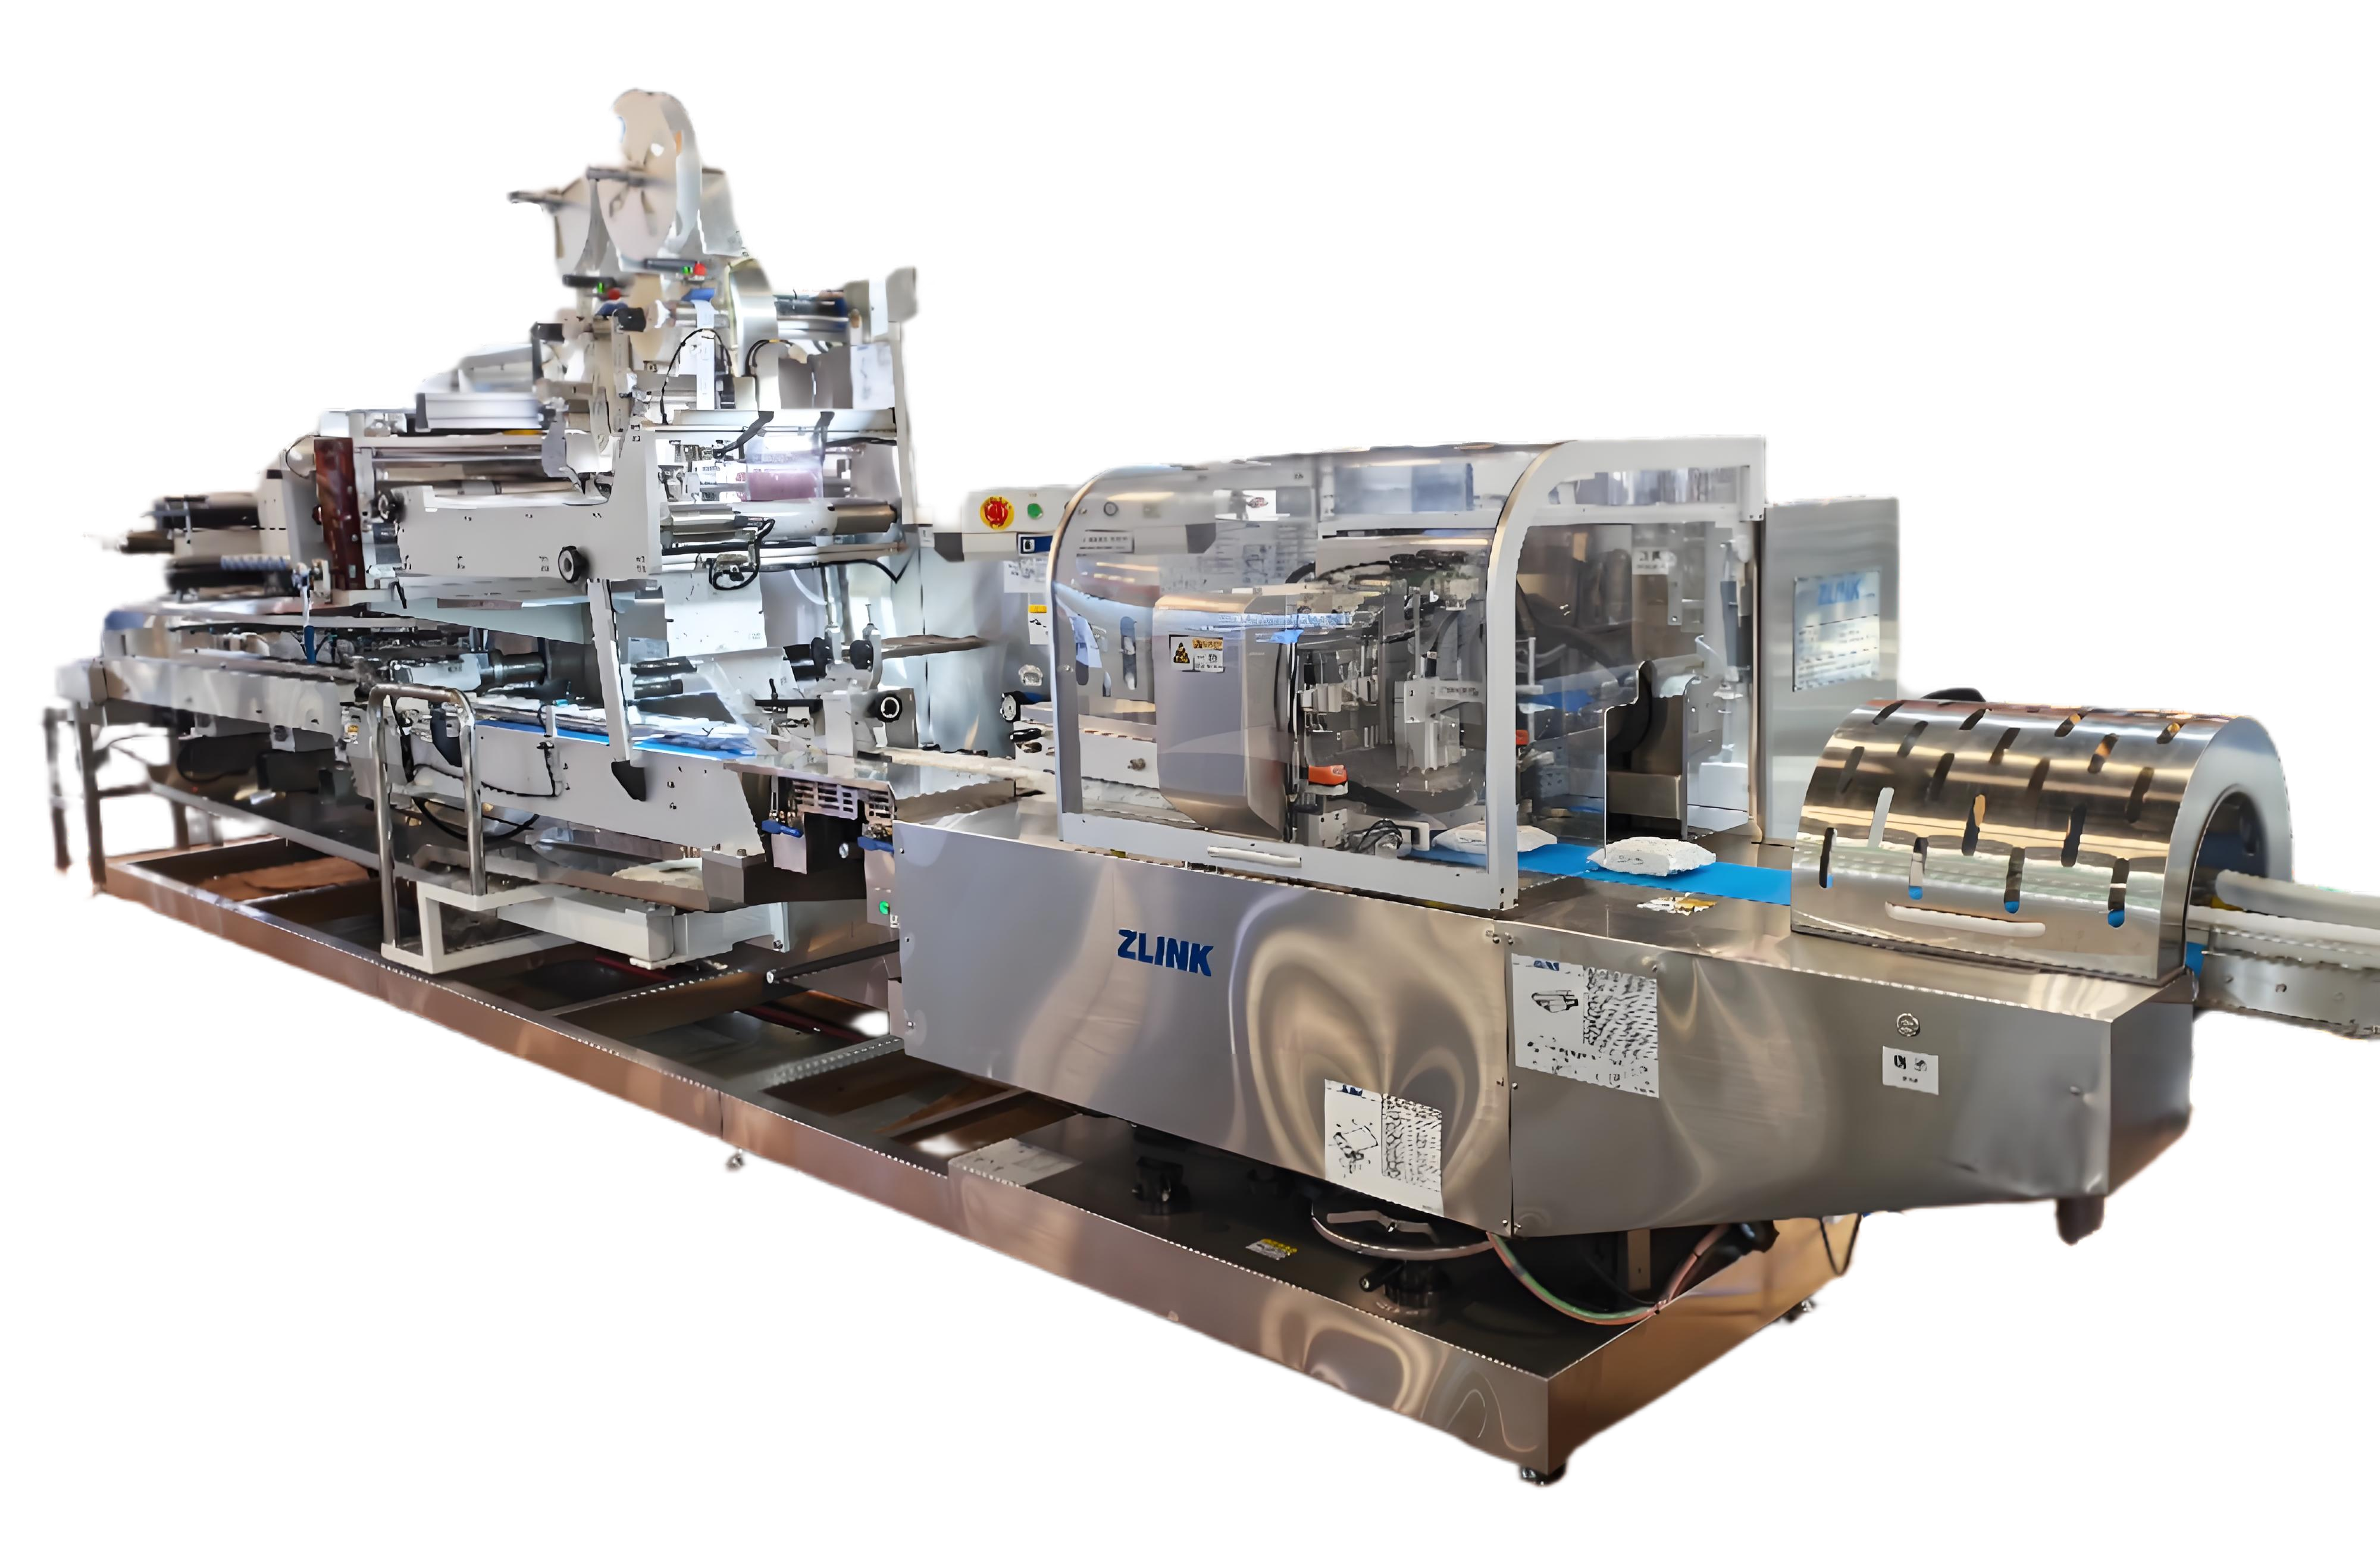
wet wipes production line setups that rely on manual checks and mismatched machines hide problems that cost time and money. I’ve seen roll unwinder tension mis-set, dosing pump calibration drift, and PLC logic cobbled together after years of “just make it run.” These aren’t tiny issues. They stack up into more scrap, slower changeovers, and grumpy shifts. From my point of view, the old fixes treat symptoms — not the cause. Look, it’s simpler than you think: tighten control where variability starts (web handling, dosing) and you stop firefighting downstream.
What’s the core snag?
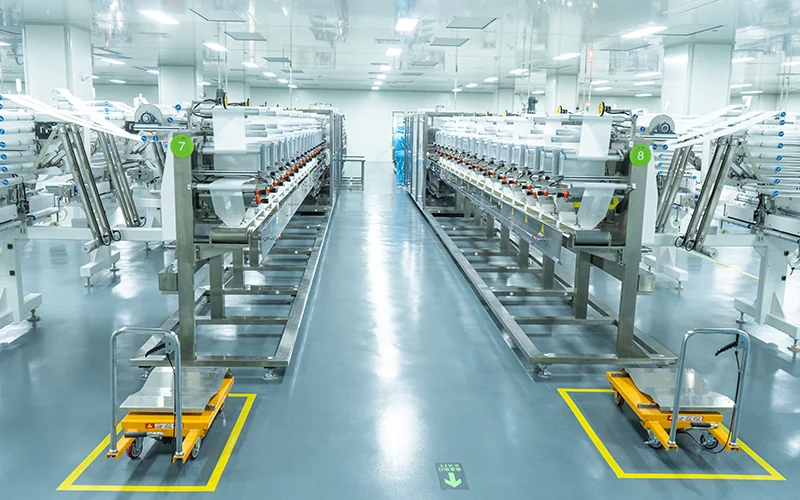
The core snag is threefold: poor data, inconsistent mechanics, and human workaround. Without reliable sensors feeding an HMI or SCADA layer, operators guess. Without standard servo motors and consistent power converters, the line fights itself. And without clear alarms and procedures, folks invent band-aids on the fly. That improvisation keeps production moving short-term — but bites you later with unpredictable yields and maintenance headaches. — funny how that works, right?
Looking ahead: future-ready wet wipes production line strategies
When I think of the next wave for a wet wipes production line, I imagine modest, practical upgrades that change the math: better sensors at the unwind, smarter PLC sequencing, and edge computing nodes that pull local uptime stats rather than waiting for a weekly report. In practice, this means a measured roll-out — retrofit one machine, tune the dosing pump feedback, then scale. We’re not swapping everything overnight; we’re choosing precise improvements that free up operators and shrink variability. That’s less flashy, more effective.
What’s Next?
Over the next 12–24 months I’d expect to see more lines with modular automation kits: standard drives, common servo motors, and clearer HMI screens so even temporary staff can spot a problem. We’ll also see simple analytics that flag trends (not just alarms), so maintenance teams act before a gearbox gives up. The benefits are concrete — quicker changeovers, fewer rejects, and calmer shifts — and that builds confidence in the crew to embrace more automation later.
Practical takeaways and how to judge solutions
I’ll be blunt: not every shiny system helps. I want solutions that do three things well — and I judge vendors by these metrics. First, uptime improvement: can they show a reproducible drop in unplanned stops? Second, maintainability: are parts and service straightforward for your team? Third, data usefulness: do you get actionable alerts (not noise)? Measure those, and you’ll avoid costly toys that look neat but don’t move the needle. If you ask me, pick pilots that change one bottleneck at a time; the wins compound.
We’ve been through the messy now and the sensible next. I’ve worked with lines that were stubborn and then turned into dependable performers — and I still get a kick out of it. For a partner with real kit and field know-how, see ZLINK.