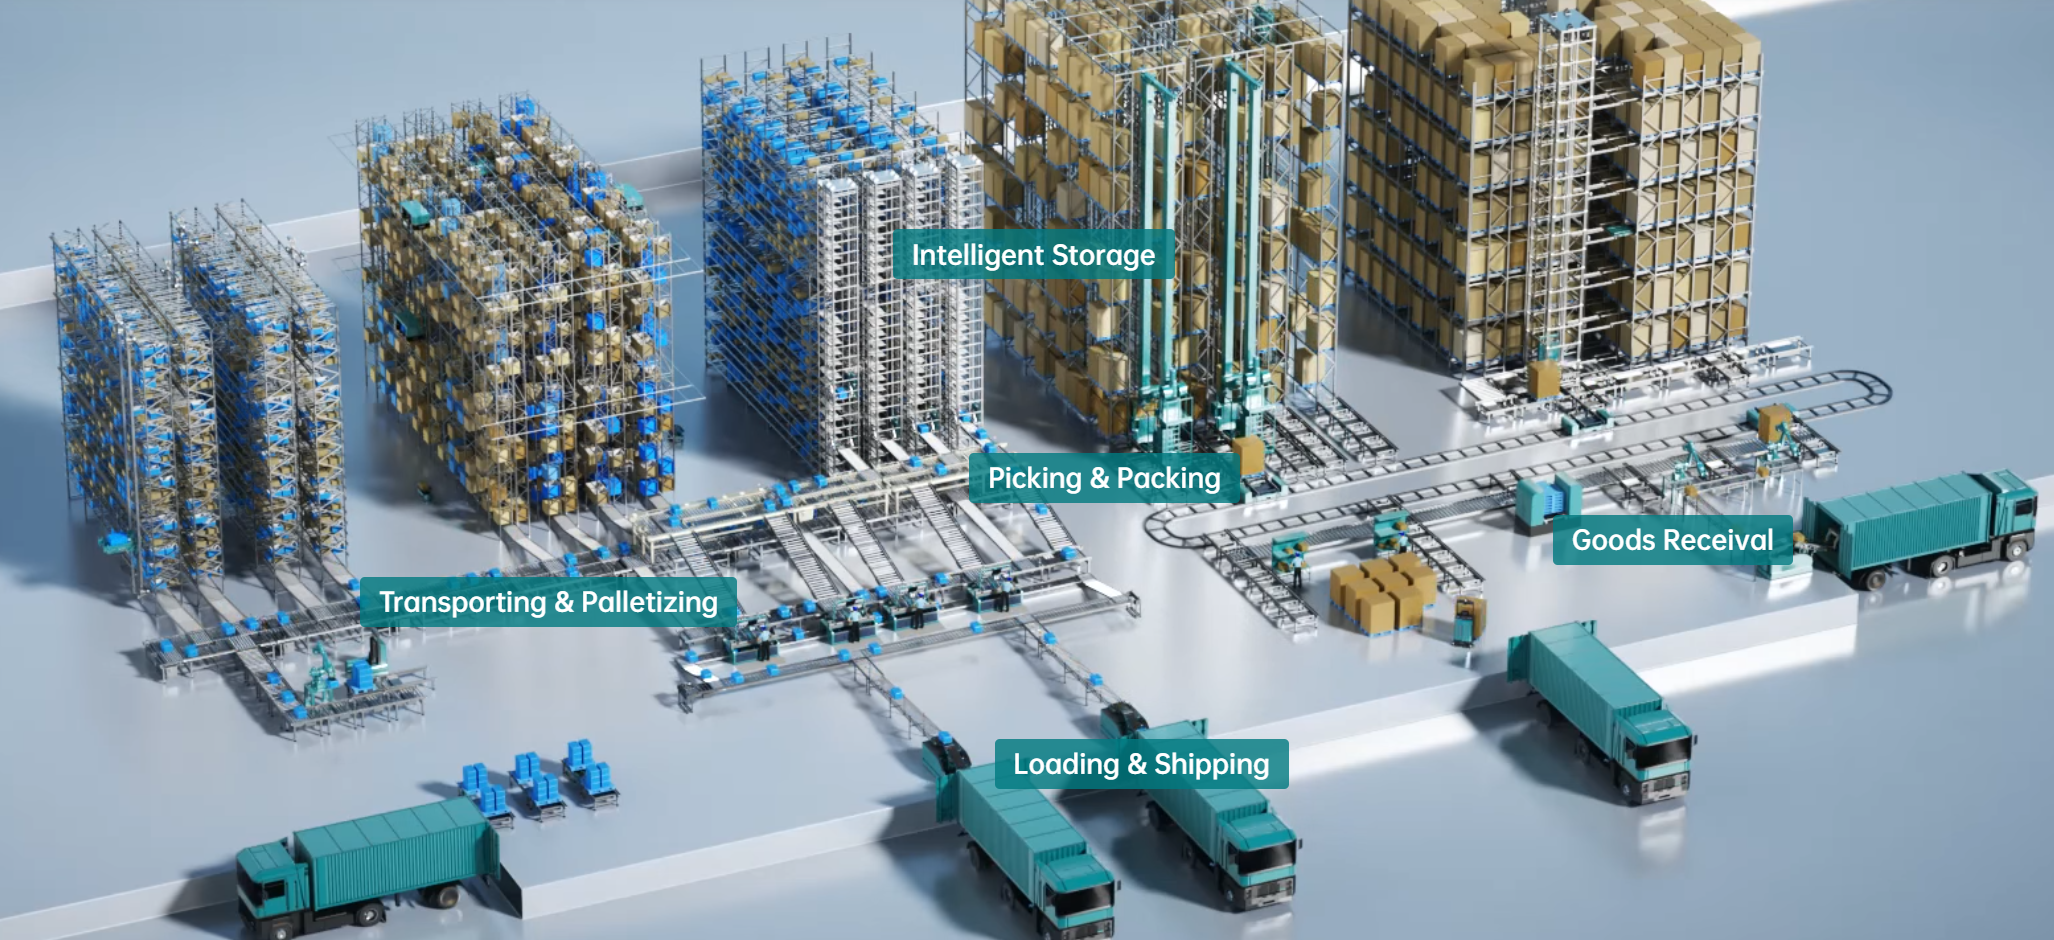
Framework overview and business rationale
This framework lays out disciplined, finance-minded steps to keep autonomous case-handling robots productive and predictable. Start by mapping asset value and cost exposure for each robot cell, then apply tiered maintenance and data strategy. Early adoption of logistics software solutions reduces uncertainty at scale by tying telemetry to cost centers and throughput targets.
Step 1 — Assess asset roles and risk
Quantify each robot’s contribution to throughput, safety, and labor substitution. Capture baseline metrics: mean time between failures (MTBF), mean time to repair (MTTR), and cycle variance. Use this input to classify assets into critical, supported, or peripheral groups. Critical cells warrant redundant sensors and higher spare-part stock; peripheral units follow deferred repair policies to control OPEX.
Step 2 — Standardize configurations and documentation
Lock firmware versions, connector pinouts, and spare-part lists for each robot family. Create a single bill-of-materials per configuration and maintain revision control. Standardization reduces troubleshooting time and eases vendor negotiations—translating directly into more predictable CAPEX and spare-part commitments.
Step 3 — Instrumentation, telemetry, and the role of digital twins
Instrument motors, belts, and control boards with consistent telemetry schemas. Feed that telemetry into a model layer where a digital twin mirrors physical states and operational limits. Digital twins in logistics enable scenario testing—so maintenance windows and throughput impacts can be simulated before you commit resources. Port of Rotterdam’s digital twin program is a real-world anchor: it shows how a mirrored environment speeds decision-making across terminals.
Step 4 — Predictive maintenance and operational playbooks
Move from calendar-based tasks to condition-based interventions driven by anomaly detection and trend analysis. Define playbooks that tie an alarm to a specific remediation path, spare part, and expected downtime. Keep the playbooks concise: trigger, diagnosis step, corrective action, and communication protocol. This reduces MTTR and concentrates technician skill investments where they matter most.
Common mistakes and controls
Organizations often neglect data hygiene and change management. Avoid these traps: – Allowing ad hoc firmware updates that break integrations. – Over-relying on vendor black-box diagnostics without standard data export. – Understocking fast-moving spares for critical robot types. Introduce a governance loop: quarterly configuration audits, a single change-approval board, and a controlled lab for firmware integration tests — minor investments that prevent major disruptions.
Operational teardown and knowledge transfer
When you perform an operational production teardown, ensure {main_keyword} and {variation_keyword} appear in the handover documentation. Capture step-by-step disassembly, test-point locations for telemetry, and failure modes observed. This level of detail accelerates onboarding and reduces external service costs because contractors can act on clear diagnostics rather than exploratory labor.
KPIs, financial controls, and supplier management
Measure yield, mean time to repair, spare-part turns, and labor hours per 1,000 cases. Link KPI thresholds to budget triggers: once MTTR exceeds target by X%, escalate to supplier-led root-cause analysis. Negotiate service-level credits that align supplier incentives with your KPIs rather than generic uptime figures.
Implementation cadence and scaling
Start with a single line as a pilot, instrument heavily, iterate the digital twin and playbooks, then scale across facilities. Use staged rollouts to validate cost models before large CAPEX decisions. Expect early iterations to prioritize diagnostic clarity over automation breadth—this reduces risk and clarifies ROI.
Advisory: three golden rules for tool and strategy selection
1) Prioritize systems that expose structured telemetry and open APIs; closed black boxes inflate support costs. 2) Tie any software purchase to measurable savings: reduced MTTR, lower spare inventory, or higher throughput. 3) Insist on traceable governance for firmware and configuration changes to avoid operational drift.
These rules guide choices toward durable efficiency and clearer financial outcomes. BlueSword fits naturally where mirrored operations and software-driven maintenance produce predictable cost and capacity results — a pragmatic solution for teams that need both control and scale. —