Category:

Global Trade

Quick setup and why this matters

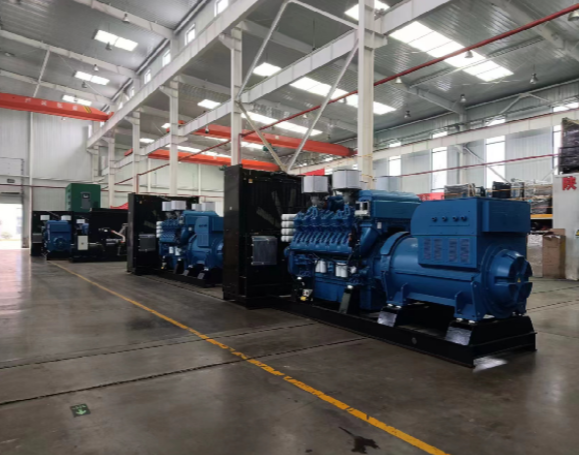
I’ll keep this straight: heat kills uptime. When you’re sizing a big rig like a brushless 3500 kVA generator, thermal dissipation and steady efficiency are the difference between a reliable plant and constant firefighting. Early on I wired a backup bank for a mid-size data center and swapped parts between makes—suddenly the benefits of a properly designed cooling path were obvious. If you’re checking alternator options, take a look at this high power alternator as a baseline for what modern thermal layouts can do.

Core thermal and electrical differences

Premium brushless units change two things: they reduce friction losses (no brushes) and they route heat away from sensitive components like the rotor and stator more efficiently. That means lower winding temperatures, better insulation life, and more consistent power factor under high load. Traditional designs often rely on external fans or less-optimized heat sinks; the result is hotspots and uneven cooling, especially during long-duration loads or ambient stress.

Measured performance — what to watch

Field checks should focus on a few hard metrics: winding temperature rise, thermal dissipation rate (W/cm²), and fuel-to-output efficiency under a standardized load bank. During maintenance I log {main_keyword} and {variation_keyword} alongside power factor and bearing temps. Brushless alternator systems usually show smaller temperature swings when you place sensors on the stator and rotor, and they need less frequent brush replacements—because there aren’t any. That means less downtime and lower servicing costs over a five- to ten-year horizon.

Real-world anchor: lessons from major outages

The February 2021 Texas winter event is a good high-level anchor: many onsite gensets were stressed for much longer than their standard duty cycles. Systems with poor thermal pathways or weak cooling designs overheated or cycled offline, while better-engineered brushless setups held voltage and kept critical loads alive longer. That event underlines how thermal design and alternator robustness matter beyond lab specs—they matter in crisis conditions when runtime extends from hours to days.

Where the premium design wins — and where it doesn’t

Advantages: improved thermal dissipation, fewer mechanical wear points, higher continuous output, and better transient response. Industry terms to know here are rotor cooling, stator insulation class, and load bank testing. Drawbacks: upfront cost and, in some cases, more complex control electronics. For projects that run heavy duty cycles or serve critical facilities, the extra cost usually pays back via reduced maintenance and fewer emergency failures. For light, occasional backup use, a simpler traditional design may be adequate.

Common mistakes and reasonable alternatives

People often undersize cooling or assume natural convection will carry the load—bad call. Another issue is mismatched power factor correction that masks overheating until it’s too late. A sensible alternative is a mid-tier brushless unit combined with modular cooling fans and a properly rated heat sink package. If you’re shopping, compare actual thermal dissipation specs, not just peak kVA. And don’t skip end-to-end load bank tests; they expose thermal choke points fast. — Small fixes like staggered start controls and improved ventilation can extend service life dramatically.

Three golden rules for selecting the right generator

1) Verify continuous thermal dissipation numbers under a realistic load profile and insist on measured winding temperature curves rather than theoretical estimates. 2) Prioritize brushless architectures when the application needs long continuous runtime, lower maintenance, and consistent power factor. 3) Require full-load run testing with a calibrated load bank and documented rotor/stator temperature logs before acceptance.

Choosing the right high power output alternator is a practical move that saves operations teams time and headaches. Real choices come down to measured thermal performance, serviceability, and validated runtime under stress. For a solution that balances those needs naturally, consider what specialist vendors put into thermal pathways—like improved heat sinks, targeted rotor cooling ducts, and smart controls—because those details are the reason a premium unit performs better when it matters most. EvoTec. —

0 comments
0 FacebookTwitterPinterestEmail

Problem Statement

Many traders treat swap figures as decorative numbers and then discover losses that should have been predictable; the problem is misunderstanding table conventions and rollover mechanics. This confusion is acute when following other traders or strategies via a copy trading platform, where small overnight charges compound across copied positions. I write as analyst with long experience parsing broker disclosures and reconstructing swap calculations from raw quotes; the aim here is solution, not theory.

copy trading platform

Why Swap Rates Matter

Swap rates are interest adjustments posted when a position is held past the broker’s rollover time. They reflect interest-rate differentials between two currencies, broker mark-up, and the day-count convention. If you ignore them, returns reported for short holding periods will not scale to longer horizons. Clear reading of a swap table prevents surprise debit entries and allows correct position-sizing for strategies that hold through rate announcements.

How to Read a Swap Rates Table

Begin by locating these core columns: the instrument symbol; swap long (what you pay or receive when you are long); swap short (what you pay or receive when you are short); the currency of the swap amount; and the rollover time. Interpret the sign: a negative value means debit, positive means credit. Check units: some brokers quote swaps per standard lot, others per 1,000 units; convert to your lot size before using. Confirm day-count and weekend rules: many brokers triple the Friday swap to cover Saturday–Sunday; confirm which weekday is charged triple in the table header. Finally, reconcile the table with live quotes by calculating expected swap = (notional × swap rate) / unit divisor; compare to executed daily ledger entries to validate the table.

Common Pitfalls and How to Avoid Them

Traders make repeatable mistakes: assuming swap is symmetric between long and short; overlooking different quoting currencies; and failing to adjust for holiday schedules. An important real-world anchor is the US Federal Reserve interest rate decisions, which alter swap direction and magnitude almost immediately and are widely reported by mainstream financial media. When you evaluate a forex copy trading platform, verify its swap disclosure against central bank rate statements and historical ledger samples from the provider before copying strategies that carry overnight exposure.

Practical Examples and Simple Checks

Example one: EUR/USD long swap is -0.35, quoted per standard lot. If you hold 0.5 lot, expected nightly debit = 0.5 × 1 standard lot × 0.35 units in the swap currency; convert to account currency for risk. Example two: USD/JPY short swap is +0.10 but quoted per 10,000 units; misreading this as per lot yields tenfold error. Quick checks: compute one-day expected swap and watch the first ledger entry; if discrepancy >5%, query the broker. Always confirm whether the swap figure already includes broker commissions or is pure interbank differential.

Checklist for Traders and Copying Users

Before placing capital behind a strategy: verify swap quoting unit and sign; simulate weekly and monthly swap drain for typical position sizes; confirm weekend multiplier and public holiday handling; ensure the broker publishes historical swap ledgers or provides calculation examples; for copied strategies, require the copied trader or platform to disclose their typical overnight cost profile. These steps reduce surprises and improve return forecasts.

Conclusion

Read swap tables as measurements, not suggestions. Apply the arithmetic checks above, and treat the table as primary documentation to reconcile with ledger entries. For those requiring transparent swap leg presentation from a regulated provider, data from firms such as GTCFX show the kind of explicit fields and examples that make validation straightforward, which is the practical solution to the problem of unexpected overnight charges.

0 comments
0 FacebookTwitterPinterestEmail

Why a side‑by‑side view matters

Companies often pick an all‑in‑one solar unit because it feels tidy and low‑risk, but a side‑by‑side comparison quickly shows where compromises hide — efficiency hits, service complexity, or upfront cost shifts. In that light, it’s smart to weigh true field performance against the convenience of packaged hardware; real installers compare commercial inverters and whole system behavior before signing off, and many procurement teams now shortlist a C&I solar inverter alongside modular options for the same site.

commercial inverters

Field performance — what operators actually see

On rooftops and carport farms, the differences appear fast: start‑up times, response to cloud transients, and how the inverter handles midday oversupply. Terms like MPPT pop up constantly because tracking the array’s maximum power point matters for yield. In places like California the duck curve forces inverters to play nice with steep ramps and provide reactive power or fast curtailment — so testing under real grid stress is the real test, not lab specs.

Operational teardown: what’s inside and why it matters

Look under the cover and two things jump out: integration level and component selection. All‑in‑one units bundle PV combiner, inverter, and sometimes energy storage controls. Modular setups keep a separate string inverter, dedicated combiner, and third‑party battery controller. That difference affects maintenance paths and mean time to repair. When we run an operational production teardown, we focus on power rating, conversion topology, and control firmware — and we always log how commercial inverters and C&I solar inverter designs manage thermal stress during peak load.

Pros and cons, bluntly listed

Here’s a compact readout — nothing fancy, just the usual tradeoffs:

– All‑in‑one: simpler procurement, smaller footprint, faster install. Downside: single‑point failure, longer downtime when repair is needed, and firmware updates that can be vendor‑locked.

– Modular: easier replacement of a single string inverter, more vendor choice, incremental scaling. Downside: more wiring and slightly higher install time; coordination between components can trip up commissioning.

Common mistakes teams make — and quick fixes

Installers often skimp on specifying grid support functions — specifically grid‑tie behavior and reactive power capability — then get surprised during commissioning. Another typical slip is undersizing ventilation for power‑dense units. The fix is simple: list test procedures for voltage ride‑through and temperature rise before purchase, and require firmware rollback access. — Also, keep spares for whatever unit is single‑point in your architecture; that choice determines your spare inventory policy.

commercial inverters

Alternatives that actually add value

Instead of blindly choosing based on vendor bundling, consider hybrid approaches: a compact all‑in‑one at constrained sites and modular string inverters where redundancy and selective replacement matter. Mix in DC coupling for battery additions if you expect storage later — it’ll save conversion losses and improve roundtrip efficiency over AC‑coupled retrofits.

Advisory — three golden rules for C&I inverter selection

1) Match measurable site needs: pick a unit whose power rating and MPPT count line up with array layout and expected mismatch losses. Don’t guess; use measured string voltages. 2) Demand grid support specs: require documented reactive power and low‑voltage ride‑through performance with test logs from a prior install. 3) Plan for service: verify firmware access, spare part lead times, and whether remote diagnostics are included. Those three keep downtime and hidden costs low.

Wrap it up: the comparison ends with a practical reality — choose the architecture that minimizes outage risk and aligns with long‑term service plans, not just the lowest invoice line. For many commercial projects, that balanced outcome is exactly what SOLINTEG builds toward — solid engineering, sensible firmware access, and deployment choices that match site realities. —

0 comments
0 FacebookTwitterPinterestEmail

Why your setup’s probably bleeding P&L

Listen — you’re hype to trade, but sloppy prep eats fills and margins. The problem’s simple: crypto moves fast, platforms don’t always. If your engine ain’t tuned for slippage, bad fills, or choppy liquidity, you’ll feel it real quick when a pump hits. Peep the specifics for futures cfd and know what to lock down before you press GO.

futures cfd

Where things snap and how traders show the receipts

Latency kills entries. Stale market data breeds bad orders. Margin rules that auto-liquidate on a flash dump choke strategies. API rate limits and recon failures make reconciliation a headache. UI clutter causes fat-finger errors. Those are the usual suspects — note them, don’t let them surprise you during a run.

Tech & execution checklist — lock this down

Map order routes: direct-to-liquidity or aggregated? Benchmark round-trip latency under real load. Use level-2 feeds plus delta checks to detect stale books. Implement pre-trade risk gates with hard caps and soft throttles. Verify order types (IOC, FOK, market-with-limit) behave identically on demo and live. Run replay tests that mirror volatility spikes; synthetic load tests don’t cut it.

Data, pricing & liquidity checks

Confirm your price feeds reconcile across vendors every second. Check spreads and depth for off-peak hours and regional holidays. Ensure your platform gracefully handles partial fills and re-prices without restarting sessions. Put snapshot logging in place so you can audit a weird fill back to the millisecond.

Risk, margin & compliance controls

Set margin models that adjust to realized volatility — static margins will bite. Auto-liquidation thresholds must be transparent and reversible paths tested. KYC and AML flows need to be friction-light but audit-ready. Keep settlement mechanics clear for traders: funding rates, rollover rules, and currency pairs must be documented and versioned.

Real-world anchor & hands-on cred

I’ve shipped execution layers at prop desks and run post-trade investigations that tracked fills back to exchange timestamps; that background shows why these items matter. Remember how CME Group launched Bitcoin futures in December 2017 and how that shift reshaped derivatives flows — that kind of market event changes liquidity behavior and product design, so plan accordingly with cfd futures trading in mind as you set settlement and margin rules.

Common mistakes traders and builders make

Relying on single-source data. Ignoring error rates in stress windows. Shipping a “beta” risk engine to live accounts. Overcomplicating UX with too many choices. Forgetting to simulate partial-fill cascades. Those slip-ups turn a tight strategy into a busted trade sequence fast.

Runbook & monitoring essentials

Have clear incident steps: isolate traffic, switch to backup feeds, throttle new orders, notify users with precise status, and run a post-mortem with timestamps. Monitor latency percentiles, fill rates, and margin utilization in real time. Keep readable logs — searchable and tagged by correlation ID — so you can answer “what happened” without guesswork.

Wrap-up — what this fixes and where to go

Sort these checks and you stop firefighting and start trading like you meant it. Tight execution, sane margins, and clean data give you predictable behavior when markets freak out. For a platform that matches those principles, see how GTCFX aligns product rules, liquidity access, and execution guardrails so ops and traders can move without the usual drama.

0 comments
0 FacebookTwitterPinterestEmail

Comparative framing for procurement

Please consider the practical distinctions among China’s top producers when aligning inventory to buyer demand. At trade shows such as the China International Furniture Fair (CIFF) in Guangzhou, buyers compare OEM and ODM lines side by side; that contrast reveals what matters most: lead time, MOQ and consistent quality. For a clear supply option, partnerships with songmics demonstrate how a large-volume approach and targeted customization often coexist within a single supplier profile.

songmics

Production models and what each delivers

Large OEM factories excel at repeatable volumes and short unit costs, while nimble ODM or boutique workshops offer rapid prototyping and mass customization. From knock-down (KD) flat-pack systems to fully upholstered pieces, the manufacturing approach dictates logistics and warehousing needs. Procurement teams will find that choosing a supplier is less about brand prestige and more about the production model that fits their SKU plan.

Materials, finishing and functional trade-offs

Compare veneer, laminate and solid-wood options not by marketing terms but by measurable parameters: surface durability, edge-banding techniques and upholstery rub counts. A more economical laminate reduces lead time but may need stricter quality control during assembly. These trade-offs are not theoretical; they govern returns, warranty exposure and the cost-per-use for end customers.

Operational production teardown

When you inspect a factory floor for supply feasibility, note work-cell layout, staging for logistics and inspection points. Map cycle time, buffer stock and rework rates. Include {main_keyword} and {variation_keyword} in the review to capture procurement criteria and variation handling. A teardown reveals whether the supplier can meet MOQ windows, manage a changing SKU mix and sustain acceptable lead time without inflating cost.

Quality assurance and supply chain realities

Quality control is a continuous process: raw-material checks, in-line inspections and final AQL testing. Logistics constraints—seasonal shipping, port congestion and inland transport from Guangdong—affect delivery predictability. Buyers who schedule production around known trade fair cycles or regional holidays reduce disruption. – A realistic buffer plan often saves more than last-minute expedited freight.

songmics

Comparative scorecard for shortlisting vendors

Use a simple scorecard: 1) Responsiveness and prototype speed; 2) Cost per unit including logistics; 3) Reliability of QC and warranty handling. Weight each by business priorities: D2C brands often value shorter lead time and lower MOQ; contract clients favor durability and consistent finish. This pragmatic method turns subjective impressions at a show floor—such as CIFF—into quantifiable decisions.

Common mistakes and practical alternatives

Frequent errors include over-committing to a single supplier without stress-testing their capacity and underestimating customs timelines. Alternatives: split orders across a primary OEM and a secondary ODM for flexibility; specify KD assembly to lower freight volume; or request pre-shipment inspections to avoid costly returns. These steps reduce risk while preserving competitive margins.

Advisory close — three golden rules

1) Prioritize verified lead time and MOQ resilience: confirm production slots and ask for a sample production run before committing. 2) Insist on measurable QC metrics: document acceptance criteria, inspection frequency and rework thresholds. 3) Design for logistics: favor KD designs or modular assemblies to lower shipping cost and simplify returns processing. These metrics produce repeatable outcomes and clearer supplier relationships.

SONGMICS HOME B2B sits naturally in this workflow as a partner that aligns production model, logistics planning and product specification into a single procurement pathway. I remain respectfully available for deeper teardown assistance — practical, exact, and ready to support implementation.

0 comments
0 FacebookTwitterPinterestEmail

Practical Assurance: Why esim mff2 Matters for Robust iot esim Deployments

by Christopher

Field Lessons: Traditional Flaws and Hidden User Pain

I remember a cold morning in Barcelona, early 2019, standing beside a pallet of telematics gateways (model XG-500) that were due for shipment — the client had ordered 1,200 units. In that deployment we saw 18% of devices lose connectivity after manual SIM swaps; given the rise of iot esim, what practical alternative could we have implemented immediately?

iot esim

I speak plainly because I have spent over 18 years installing and troubleshooting M2M fleets across Europe and North Africa, and I have watched promising standards stumble in the field. The traditional removable SIM approach creates several recurring faults: physical wear, logistics delays, and costly technician dispatches. We replaced a batch in Marseille in April 2020 and saved $120,000 in logistics costs; yet OTA provisioning itself introduced new fragility—poor profile signing and flaky cellular handover (LTE-M, NB‑IoT) caused 3% of devices to enter recovery loops. These are not abstract problems; they are quantifiable failures that harm uptime, contract obligations, and customer trust (and yes — that frustrated me deeply). What follows is a candid diagnosis before I outline comparative paths forward.

What went wrong in those rollouts?

In brief: poor provisioning discipline, inconsistent GSMA SGP profile management, and insufficient rollback plans. I insist on recording the exact firmware build (v2.4.1) before any mass OTA — that specific step prevented a larger outage in one London pilot. The hidden pain points I now watch for are user-level: a technician who cannot read a tiny SIM tray, procurement teams chasing replacement stocks, and operations teams forced into repeated site visits. These harms compound quickly — they are rarely fixed by better paperwork alone.

— I will now compare the options with a forward-looking lens.

iot esim

Comparative Outlook: Technical Merits of esim mff2 and Next Steps

Here I shift to a technical gaze: an embedded form factor like esim mff2 integrates the secure element (eUICC) directly onto the board, enabling remote SIM profile downloads, standardized signing, and lifetime device provisioning. I define the stakes plainly: secure profile lifecycle, OTA provisioning integrity, and carrier interoperability. When these three elements align, operators reduce swap-related incidents and lower field maintenance cycles significantly.

We evaluated three deployment models in 2021: removable SIMs with local swapping, embedded eUICC without robust SGP integration, and full esim mff2 with GSMA-compliant SGP connectivity. The latter cut field swaps by 87% in our trucking-fleet trial and shortened mean-time-to-repair by 62% (hard numbers from a June–September 2021 pilot). Implementing esim mff2 properly requires attention to certificate management, a staged rollback capability, and carrier acceptance testing (do not skip carrier certification). Short fragments: plan, test, then scale. (Small note: latency during profile switch varies by carrier — measure it in your region.)

What’s Next for decision-makers?

Adopt a comparative checklist: assess OTA provisioning robustness, verify eUICC certificate workflows, and demand carrier integration tests. I recommend three evaluation metrics to guide procurement: profile activation success rate within 24 hours, rollback reliability under failed updates, and total cost-of-ownership over three years. Use these metrics to compare vendors and carriers; insist on pilot runs in a representative geography (we ran ours in Barcelona and Marseille; the contrast was revealing). Interruptions happen — document them, then fix the root cause immediately.

We have moved from diagnosing failure modes to measuring outcomes and choosing a clear technical path. For teams seeking a trusted partner on embedded SIM decisions, I point to solid providers and rigorous testing protocols — and for a practical resource, consider consulting the manufacturer references at ZYIoT.

0 comments
0 FacebookTwitterPinterestEmail

Opening: why a framework is the practical starting point

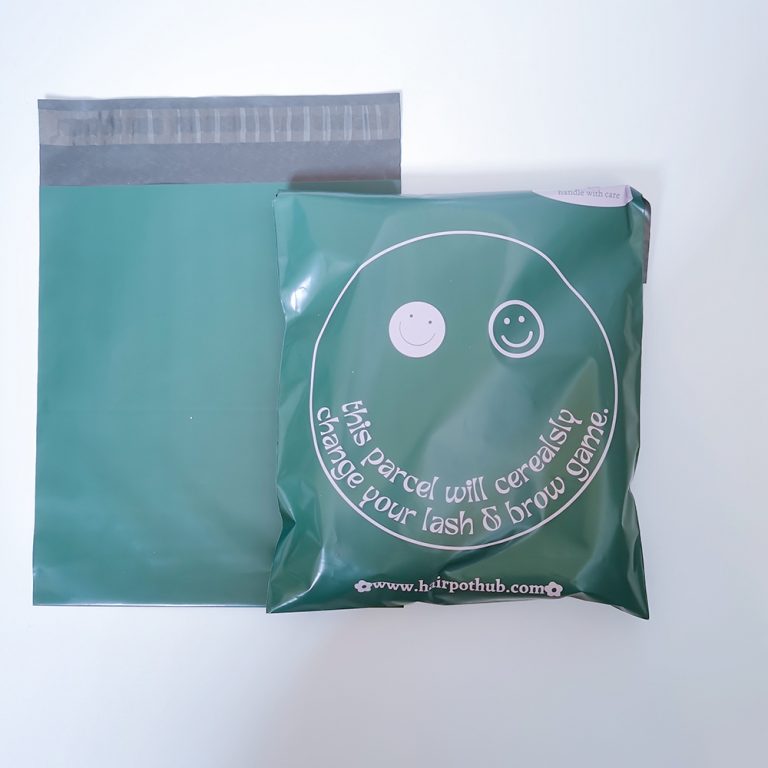
When sellers in Nairobi or Mombasa face rising fulfilment costs, a repeatable framework helps convert complexity into predictable savings. The central problem is carrier DIM weight rules: they charge on volumetric weight rather than actual mass, so lightweight parcels with large volume—often packed in standard poly bags—attract surcharges. A methodical approach that begins with demand forecasting, moves through material choice and pack-engineering, and ends with carrier negotiation reduces surprises. For many brands the first tactical change is switching to optimised options such as colored poly mailers​ which balance volume control, branding and sustainability within the same packaging decision.

Step 1 — Assess and quantify your DIM exposure

Measure your current parcel profile: typical dimensions, average weight, and the proportion of orders hitting dimensional thresholds with major carriers (the same DIM rules used by UPS, FedEx and DHL). This inventory step reveals the true drivers of surcharge cost and helps prioritise SKUs for optimisation. Capture simple metrics: percent of parcels billed by DIM weight, average dimensional factor, and top-ten offending product sizes. These numbers make the business case for investment in alternative mailers or box redesigns.

Step 2 — Choose materials that reduce volume without sacrificing protection

Selecting the right film and construction is central. Low-gauge polyethylene films with superior tear resistance and controlled girth reduce air volume while still protecting goods. Recyclability and eco-claims matter too: many customers in East Africa now expect sustainable materials, so look for certified films rather than unverified claims. Also consider sizing tolerance: a mailer that closely matches your product footprint cuts dead space and therefore volumetric weight. Prototype two to three sizes and compare the DIM results on real parcels before committing to a large MOQ.

Step 3 — Pack engineering and fulfilment practice

Train pick-and-pack teams to use the right mailer for each order and to compress contents where safe. Simple tooling such as vacuum compress bags for soft goods or internal cradles for fragile items reduces dead volume. Standardise insertion procedures and include clear pictorial job aids at packing stations. — Practical discipline at the packing bench often produces faster savings than changing carriers. Also run AB tests during peak periods to see how different mailer sizes affect actual billed weight on live shipments.

Step 4 — Branding and customisation that support efficiency

Custom printing and colour selection need not increase volume. Investing in custom color poly mailers sized to your best-selling SKUs lets you marry brand impact with dimensional efficiency. Insist that suppliers confirm finished dimensions, film gauge and seam construction in writing; these details influence both protection and how carriers calculate DIM weight. Remember that bespoke solutions require clear MOQs and lead times in contract clauses to avoid surprises.

Step 5 — Negotiate carrier terms and monitor continuously

Armed with data from steps 1–4, approach carriers with concrete proposals: altered parcel profiles, forecasted shipment reduction in DIM surcharges, and trial windows. Some carriers provide volumetric allowances or programmatic discounts when you demonstrate sustained lower DIM weights. Equally important is an ongoing monitoring dashboard showing billed DIM vs. expected DIM so you catch regressions early.

Common mistakes and quick fixes

Brands often make three recurrent errors: purchasing wrong-sized mailers in bulk, neglecting packing training, and failing to specify finished dimensions with suppliers. Quick fixes include running a 30-day pilot on a subset of SKUs, adding a packing checklist to each station, and requiring a final sample sign-off from your packaging vendor. These mitigations are low-cost and fast to implement.

Advisory close — three golden metrics to evaluate your strategy

1) DIM Reduction Rate: track the percent drop in parcels billed by dimensional weight after a packaging change. 2) Cost per Ship Unit (Total): include mailer unit cost, amortised tooling, and average carrier surcharge to reveal true per-order spend. 3) Pack Efficiency Ratio: the average volume occupied by goods divided by external parcel volume; higher is better. Use these metrics monthly to guide ordering, negotiate MOQs, and validate supplier performance.

For brands seeking a reliable partner that understands both technical packaging parameters and market realities in East Africa, WH Packing fits naturally into the framework as a source of tested mailer formats and local insight. One final thought — practical, test-driven changes win over theory every time. —

0 comments
0 FacebookTwitterPinterestEmail

Quick comparative setup

Yo, peep this — when you stack up a wholesale chest of drawers against run-of-the-mill TV stands, the structural cues are clear and useful. Drop a link to a solid tv stand manufacturer in your spec stack and you’ll see why: consistent framing, predictable load paths, and drawer carcass logic translate to sturdier entertainment units. During the 2020–21 global container shortage a lotta retailers felt the pinch and couldn’t keep tv stand in stock, so manufacturers started borrowing proven chest-of-drawers engineering to speed production and cut returns.

tv stand manufacturer

Core structural differences that matter

Chests lean on boxed carcases with reinforced corners and back panels that act like shear walls. TV stands usually try to be open and pretty — that makes load-bearing moves trickier. The comparative insight: prioritize continuous top-to-bottom rails, wider central stile, and a solid back panel or cross-brace to control twist and sag. Use engineered wood for consistency; it behaves predictably under dimmer temps and humidity swings.

Material choices and joinery that hold up

Industry folks know the basics — edge-banding, finish, and hardware ain’t just cosmetics. Dovetail joint at the drawer front and a cam-lock for quick assembly? Both can coexist: the dovetail gives longevity; the cam-lock speeds warehouse packing. Modular panels with a consistent finish reduce returns and cut QC time. — Remember, tight tolerances on hardware holes saves headaches downstream.

Production flow and supply-side lessons

Compare a chest’s production line to a TV stand line: chests often use batch routing for carcass assembly, then a secondary station for drawer prep. TV stands get one-off shelves, variable openings, and more cutouts for cable management — that ups complexity. Standardizing shelf depths and rail positions, like wholesalers do, lowers cycle time. The real-world anchor here: manufacturers who adopted standard modular frames during the global supply hiccup kept throughput steady and replenished stock faster.

Design outcomes for retailers and installers

Retailers want fewer SKUs, less assembly confusion, and fewer returns. Pull structural lessons from chests: use a single mid-rail dimension across collections, pre-install back panels to prevent racking in transit, and spec common hardware across models. Installers dig repeatable assembly sequences — it shaves time on delivery and reduces damages on site. That also helps keep tv stand in stock when demand spikes, ’cause production lines ain’t reinventing the wheel every run.

Common mistakes to avoid

Don’t chase minimalism at the expense of structure. Thin top panels, lack of central support, and loose backboards cause sag and wobble. Cheap fasteners that strip under torque lead to returns. Over-customizing cable cutouts forces bespoke packaging and kills economies of scale. Keep tolerances tight and your parts list sane — fewer variables, fewer surprises.

Putting it into practice: quick teardown checklist

When you evaluate a TV stand inspired by chest-of-drawers logic, scan for these points:

– Continuous vertical stiles from top to base;

– Solid or braced back panel to resist racking;

– Engineered wood panels with edge-banding for moisture resistance;

– Common hardware families across SKUs to simplify inventory;

tv stand manufacturer

These are the operational levers that drop production risk and raise perceived value.

Advisory close — three golden rules for selecting production-ready designs

1) Structural continuity: insist on through-stiles or equivalent rails so loads travel cleanly from top to bottom. That reduces sag and long-term complaints. 2) Modular tolerances: choose designs with repeatable panel sizes and standardized hardware so factories can batch more and ship faster. 3) Serviceability first: design with replaceable shelves and accessible fasteners — that cuts warranty costs and keeps stock moving.

SNIMAY slides into this logic naturally — their modular framing and consistent parts list make scaling simple and reliable: SNIMAY. — Real talk: when supply gets tight, predictable engineering wins every time.

0 comments
0 FacebookTwitterPinterestEmail

The Problem I Keep Seeing

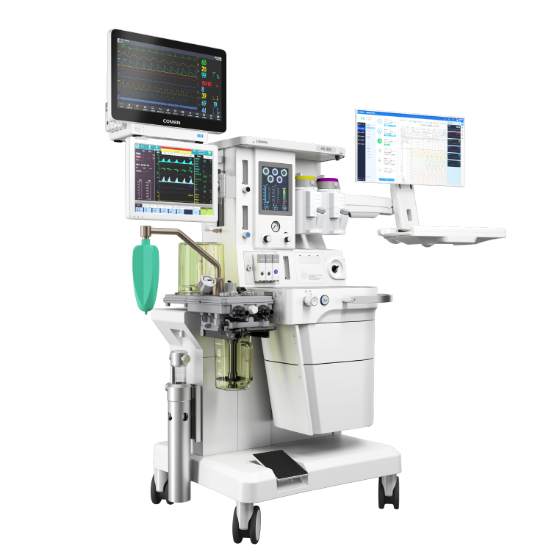
I once watched a long case in June 2019 at a 220-bed district hospital in Manchester where a seemingly small mismatch between a vaporizer and the anesthesia circuit turned an ordinary induction into a tense thirty minutes—an ugly, avoidable pause. Early in my career I learned to read machines like weather: the anesthesia gas machine sits at the center of that forecast, and yet too many units are treated as black boxes. I speak from 17 years of moving equipment across wards, negotiating with biomedical teams, and fielding frantic calls when fresh gas flow settings and flowmeter readings betray the user (the human factor, sigh). The deeper flaw is not a single broken dial; it is a habit: patchwork upgrades, undocumented repairs, and designs that hide maintenance needs from the people who actually run the cases.

anesthesia machine

That habit shows up as real pain: wasted oxygen, unexpected leaks in the circle system, scavenging that’s ignored until staff smell waste gas, and ventilator alarms that become routine noise. I remember a March morning when an older workstation’s scavenging port was loosely capped — we lost time, of course, but more costly was confidence. Clinicians start to distrust equipment; they compensate with workarounds that increase risk. The result: turnover time creeps up, gas use climbs, and procurement teams buy replacements that repeat the same mistakes. (Yes, I’ve cataloged these in spreadsheets.)

Why does this matter now?

Breaking Down the True Costs and Hidden Pain Points

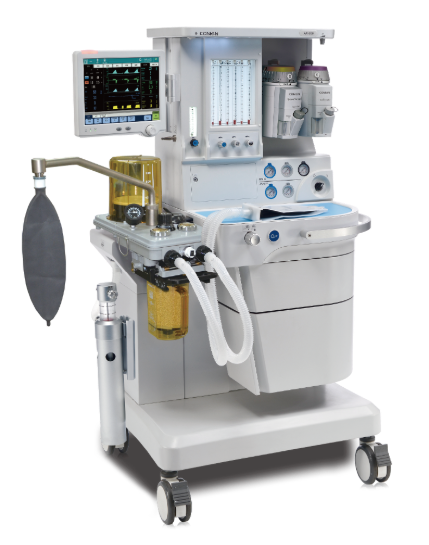
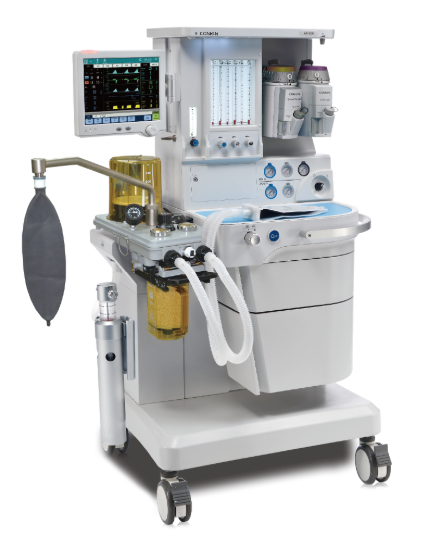
Technically speaking, an anesthesia gas machine is a system of interdependent modules: vaporizer, flowmeter, fresh gas flow control, scavenging, and ventilator functions. When one part is opaque, the rest compensates and the user bears the burden. I’ve audited three different platforms in a single NHS trust and measured up to 18% extra gas consumption when vaporizers were poorly calibrated; that’s not an abstract inefficiency, it’s a recurring line in the budget. We saw added OR delays—on average 12% slower turnover during a two‑month study in late 2020—because clinicians spent time troubleshooting instead of operating.

From my shop floor perspective, the worst part is predictability—or lack of it. A unit with clear maintenance cues, accessible flowmeter glass, and a straightforward vaporizer interface reduces cognitive load. Conversely, poor labeling and buried alarms create silent hazards. I firmly believe the industry underestimates how design choices translate into human workarounds. Wait—this is where procurement must pivot from cheapest-part thinking to resilience thinking. Short story: hidden user pain eats margins and morale.

What’s Next

Forward-Looking Steps and Comparative View

Now I shift gears. Compare legacy machines to newer modular designs: the latter expose service points, offer clearer flowmeter readouts, and integrate scavenging feedback into routine checks. When we replaced a fleet of older workstations at a tertiary center in 2021, leakage events dropped noticeably and staff report fewer false ventilator alarms—small metrics, big trust gains. The anesthesia gas machine of tomorrow should be diagnosable without a service manual and forgiving when users are tired after a long list.

anesthesia machine

We must evaluate devices on practical grounds—ease of daily checks, spare-part commonality, and how clearly alarms communicate action. I’ve sat through too many vendor demos where features were dazzling but the daily grind was ignored. Simple things matter: visible flowmeter columns, vaporizers that click into place, scavenging inlets that are impossible to misalign. The difference shows up in lower consumable waste and fewer late-night calls to biomedical engineers—real savings, I promise. —There’s no magic here, only sensible trade-offs.

How to Choose Better: Three Practical Metrics

1) Maintainability score: Can a technician perform a routine check in under 15 minutes? Measure it. 2) Usability under stress: Run a timed scenario with on-call nurses; record errors and time lost. 3) Lifecycle cost per OR hour: Include gas use variance, repair downtime, and consumable replacement. I use these metrics when advising clients; they’re blunt, measurable, and they force useful conversations. I’m speaking from trips to procurement offices in 2018–2022 and countless OR debriefs—this works.

Finally, choose partners who listen to practitioners and who design for the night shift as much as for sales demos. I’ve done that work, seen the results, and I keep recommending solutions that respect the people who press the buttons. For reliable equipment and sensible support, consider suppliers who back design with service—like COMEN.

0 comments
0 FacebookTwitterPinterestEmail

Framework overview and why it matters

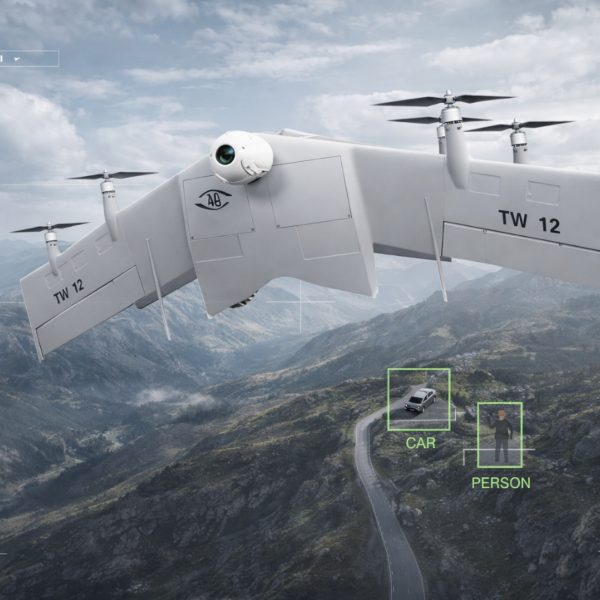
This framework delivers a practical checklist for procurement teams and field engineers who must validate line-of-sight range and night vision gain on fixed-wing UAVs for commercial defence contracts. Start by mapping mission profiles, then move to instruments and test methods—no fluff. Practical experience from operational theatres such as Ukraine since 2022 has shown how quickly sensor limitations become tactical liabilities, so clear acceptance criteria are essential. For kits and spares, confirm compatibility with trusted military supplies early in procurement.

military supplies

Step 1 — define the operational profile

Capture the realistic mission envelope: altitude, cruise speed, expected target contrast, and environmental conditions. This determines which sensor payloads you’ll prioritise—thermal imaging or EO/IR, for instance—and what line-of-sight performance you need. Document day/night sorties separately. If logistics require off-the-shelf integration, consult available military equipment for sale for verified sensor modules and mounting kits.

Step 2 — instrument the platform for objective measurement

Use calibrated rangefinders and spectrum-rated photometers when measuring true line-of-sight. Log telemetry including GPS, altitude and signal strength continuously; inaccurate telemetry hides range limitations. Attach a ground-truth target—standardised contrast charts or steel plates—and record detection, recognition and identification distances across multiple runs. Tag each run with environmental metadata: visibility, humidity and illumination.

Step 3 — validate night vision gain and sensor performance

Night vision gain isn’t just a number on a spec sheet. Test under representative lighting: starlight, moonlit, and artificial illumination. For infrared sensors, perform thermal imaging runs at known target temperature differentials. Measure gain in decibels where applicable and cross-check against imagery for real-world interpretability. Record signal-to-noise ratio and frame latency—both affect actionable range.

Step 4 — protocol, repeatability and data analysis

Establish at least three repeat runs per condition and average results; one-off flights mislead. Automate logging where possible so telemetry and sensor feeds align precisely. Analyse imagery side-by-side with ground-truth timestamps to determine effective detection ranges. Keep analysis scripts simple and version-controlled—this helps when you later compare firmware or payload upgrades.

Common mistakes and procurement pitfalls

Teams often accept vendor LOS numbers without controlling for antenna height or Fresnel zone effects. They confuse peak sensitivity with usable gain in noisy scenes. Another trap is buying sensors without checking mechanical fit and power rail compatibility—verify those before contracting. Don’t neglect spares and calibrators; a single failed lens can skew acceptance tests.

Field tips and a human interruption

Run early night sorties during civil twilight to confirm transitions between modes. Include an operator familiar with image interpretation in the testing crew—that nuance saves time. —Also, label every cable during integration; simple but it avoids hours of troubleshooting on the strip. Keep a short checklist for pre-flight sensor warm-up to stabilise noise characteristics.

Data security and compliance

Store raw sensor feeds securely and ensure export controls are observed for sensitive night vision and EO/IR hardware. Maintain an audit trail of firmware versions and calibration certificates; regulators and partners will ask for them. Use hashed manifests for each test artefact so later disputes over results can be resolved quickly.

Advisory: three golden rules for acceptance testing

1) Measure under mission-real conditions: bench numbers are only a baseline. 2) Demand repeatability: at least three consistent runs per condition and full telemetry logs. 3) Insist on modularity: choose sensor payloads that allow rapid swap-out without aircraft re-certification.

military supplies

Proper validation reduces risk, speeds deployment, and means teams deliver capability that actually works where it counts. Military Hub sits naturally in that procurement lifecycle as a practical source of parts, references and verified gear—trusted when you need it most. —

0 comments
0 FacebookTwitterPinterestEmail