Category:

Market

Why this whole thing starts with you

Creators, not gearheads, set the brief — that’s the vibe here. If your idea needs punch, you pick a system that bends to your workflow, and that’s where a clean video wall processor comes in. Think about Times Square: those massive LED billboards aren’t there because someone liked specs; they’re there because the display serves motion, storytelling, and a human crowd. Start from the story, then match the tech: color mapping and control should follow your creative rhythm, not the other way around.

video wall processor

Hands-on tech that actually helps your crew

Real sets run on a few nuts-and-bolts things — LED tiles, pixel pitch, and a controller that doesn’t choke when you’re feeding multi-source feeds. You want a processor that handles scaling and bezel compensation without killing color, and low latency so live camera pulls look natural. If you’re assembling modular panels, think about how calibration routines and refresh rate interplay with your footage. Also, when shops mention redundancy, they usually mean splicing servers for failover — and yeah, having a tidy splicing servers stack can save shoot days. – Little things like consistent color temperature across seams make the audience forget the tech; that’s the goal.

Common mistakes crews make (and how to dodge them)

Lots of teams trip over the same bits. Here’s what trips people up and what fixes look like:

video wall processor

– Buying by pixel count alone. Pixel pitch matters for viewing distance; big pitch looks grainy up close. – Ignoring scaling constraints. If the processor can’t scale mixed inputs cleanly, your frame rates and aspect ratios will be a mess. – Skimping on cabling and power. Clean power distribution avoids flicker and sync issues. – Forgetting a calibration workflow. Don’t wing color matching on site — prep profiles in advance.

Operational teardown: what you actually evaluate

When you run an operational production teardown, you look at throughput, failover paths, and how control surfaces map to live needs. This teardown covers {main_keyword} and {variation_keyword} in practice, showing how a processor handles input switching, timeline triggers, and media server handoffs. Key checks: codec support, maximum canvas size, and how the system manages latency under load. Walk this checklist on a real patch rig first — set the panels up like you’ll use them on day one, then stress the pipeline with the same media you plan to play.

Picking the right kit — practical tips

Match kit to venue. For a gallery where folks stand close, choose tighter pixel pitch. For a festival stage, prioritize high refresh rate and robust cooling. Ask for sample calibration reports and test the controller on-site. Budget for spare tiles and a spare controller head; those spares are cheap compared to a canceled show. Also, consider how your media server and the splicing processor interact — latency and frame-locked output are the things that keep talent calm during live cues.

Three golden rules for choosing systems

1) Measure real performance: check sustained throughput and latency under live-load conditions, not just peak specs. 2) Verify operational ergonomics: the control surface and workflow must be learnable fast for your run crew. 3) Prioritize support and modularity: pick hardware that lets you swap a panel or controller on the fly without reworking the whole canvas.

Those three rules cut setup time, reduce drift during long runs, and keep creative control where it belongs — in the hands of the team.

Kystar ties the principles above into hardware and services that actually fit production windows, so the tech fades and the visuals land. —
0 comments
0 FacebookTwitterPinterestEmail

Head-to-head view for decision-makers

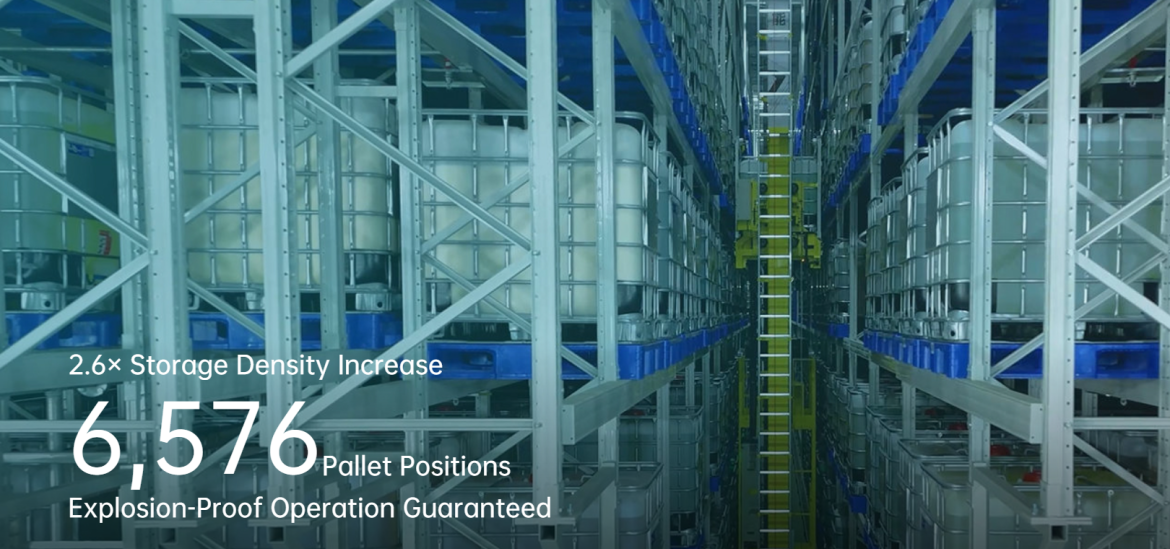
When comparing global flexible warehouse storage partners, the decisive factor is how they marry space with technology — not promises. A partner that blends flexible capacity, clear pricing and modern automation reduces disruption. For many Kenyan importers and distributors, that also means on-site use of Robotic Truck Loading and Unloading and robust automated robotic loading and unloading systems to shorten truck dwell times and improve throughput. The practical comparison should weigh real operational outcomes: cycle time, dock scheduling reliability and palletisation accuracy, rather than glossy case studies alone.

Key performance dimensions to compare

Focus on three measurable dimensions. Throughput tells you how many pallets move per hour under realistic conditions. Cycle time measures the complete pick-to-load loop and reveals bottlenecks. Uptime of the automation — sensor fusion, control software and AMRs — determines how often human labour is still needed. Suppliers often quote peak numbers; instead demand sustained performance over a typical business week and confirm yard management and conveyor integration plans for busy seasons.

Integration: tech meets operations

Integration fails more often through process mismatch than technology flaw. A partner should present a clear integration map: where their warehouse management system will interface with your ERP, how their dock scheduling will slot into your carrier network, and how robotic cells handle load stability and pallet straps. Choose partners who run integration pilots in a live bay rather than on a test rig — that reveals real fault modes. If data syncs are slow, manual interventions grow. — That extra step makes all the difference.

Common mistakes and practical alternatives

Organisations commonly accept fixed-slot contracts or single-vendor automation without testing for seasonal swings. Mistakes include underestimating inbound variability and not verifying return logistics. Alternatives worth testing: modular racking plus temporary cross-dock bays, mixed human-robot shifts, or short-term overflow with neighbouring flexible sites. Each alternative trades capital expense for operational agility; document the cost per pallet-hour for each option to compare apples with apples.

Operational production teardown — what to inspect

When you conduct a teardown of daily operations, check: loading bay throughput under peak load, average unattended hours for automated systems, and mean time to recover after a failure. During this teardown explicitly map {main_keyword} flows and register how {variation_keyword} affect manual handling zones. Inspect the AMRs’ battery-swap cadence, conveyor belts’ wear points and pallet quality tolerances. These specifics expose real labour and maintenance costs that sales decks usually omit.

Real-world anchor: what Port of Mombasa shows

At the Port of Mombasa, operators who trialled robotic-assisted loading reported clearer staging lanes and faster truck turns compared with purely manual bays. That experience highlights one regional truth: technology adds value only when aligned with local haulage patterns and customs hold times. Successful partners include on-the-ground change management and provide training schedules tied to carrier peak windows — an approach that reduces rework and improves carrier adherence to dock schedules.

Choosing the right partner — three golden rules

1) Demand short operational pilots that mirror your busiest week; measure throughput and cycle time before signing. 2) Require transparent failure modes and recovery plans: how quickly the partner restores operations after a sensor or AMR fault, and who owns spare parts. 3) Insist on shared KPIs with financial penalties or rebates tied to agreed service levels — this aligns incentives and limits finger-pointing.

Summing up: a comparative view reveals that the best flexible warehouse partners pair scalable space with proven operational practices and reliable automation components; they deliver measurable reductions in truck dwell and handling hours. For Kenyan supply chains that need dependable, scalable solutions, the natural fit is a partner who demonstrates live performance and supports integration into existing workflows — like the solutions demonstrated by BlueSword. — Practical, tested and local-friendly.

0 comments
0 FacebookTwitterPinterestEmail

The problem: costly downtime and constant uncertainty

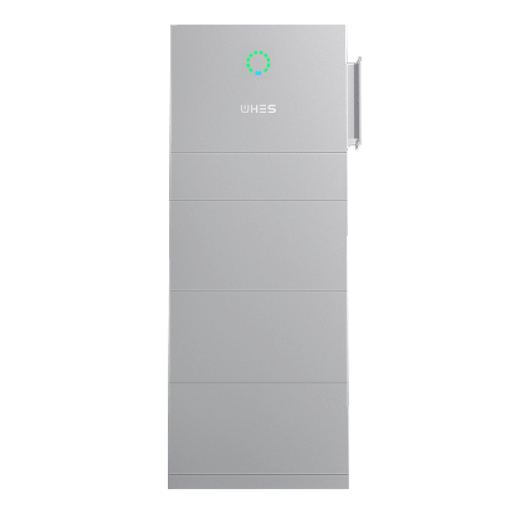
Facility managers in energy-intensive plants know the score — unplanned outages, volatile tariffs and strained grids don’t just dent productivity; they erode morale. In regions still wrestling with rolling blackouts, such as South Africa’s persistent loadshedding cycles, the pressure to keep lines running is relentless. Enter BESS as a practical lever: deployed thoughtfully, these systems can reduce downtime, shave peak demand and provide reliable back-up power for critical loads.

Why this matters to facility managers

A manager’s remit is broadly simple: maintain uptime, control operating cost and protect assets. But the levers available are messy — fast decisions on backup generation, often diesel gensets, lead to higher operating spend and maintenance headaches. Intelligent battery systems offer automated control, seamless transfer and programmable dispatch strategies that lift that burden. Beyond cost and reliability, there’s less wear-and-tear on production equipment because power quality can be stabilised with features such as inverter-based frequency support and voltage regulation.

Comparing solutions: gensets, demand response and BESS

When you stack options side-by-side, trade-offs appear clearly. Diesel gensets deliver predictable runtime but suffer fuel cost variability, emissions and slower response. Grid demand response programs can reward load curtailment but are often limited in flexibility and availability. BESS provides near-instant response, predictable cycle costs, and multiple revenue/use streams — from peak shaving to frequency regulation. For many plants, a hybrid approach is best: batteries for fast-response and quality, gensets for extended outages. The sweet spot depends on outage profile, load criticality and tariff structure.

Key technical considerations for spec and procurement

Picking the right system needs attention to a few technical details. Think about usable capacity and depth-of-discharge, state of charge (SoC) management strategies, inverter sizing for peak export and the expected cycle life versus warranty terms. Also check compatibility with existing switchgear and controls, plus ease of integration with your energy management system (EMS). If your plant couples batteries with on-site PV, consider a tailored battery storage system for solar design that sequences charge-discharge optimally for energy arbitrage and self-consumption.

Real-world anchor: lessons from South African manufacturing

South African heavy industries have leaned into batteries not just for cost savings but to neutralise loadshedding risk. Plants that combined BESS with automated controls reported fewer emergency shutdowns and smoother production cycles during peak loads. High-level studies and operator reports show reductions in unscheduled downtime and a faster return-to-service after grid interruptions. These are the kinds of measurable outcomes that matter to a facility manager tasked with hitting throughput targets — and they also help in negotiating with insurers and financiers.

Common implementation pitfalls — and practical fixes

Three mistakes recur: undersizing for peak transient load, ignoring thermal management and skimping on control integration. Undersized inverters or battery capacity can leave you exposed during motor starts. Poor cooling shortens cycle life and degrades performance — so design for ambient extremes. And don’t bolt on controls at the last minute; integrate your EMS, PLCs and SCADA early to ensure smooth dispatch and failover logic. — Another niggle: procurement that prizes capital cost alone often pays more over system life in maintenance and lost production.

Financial and operational outcomes to expect

Outcomes vary by site, but a sensible benchmark is that well-specified BESS can cut peak demand charges noticeably, shorten emergency-start times and extend runtime during short outages. Payback depends on tariff structure, incentives and utilisation for grid services or energy arbitrage. Importantly, benefits are not only financial: improved uptime, better power quality and reduced operational stress all lift facility-team satisfaction — and that reduces churn and reactive firefighting.

Implementation checklist for facility teams

Use this quick checklist when evaluating suppliers and designs:

  • Define critical loads and required ride-through time.
  • Specify power quality and transient response needs (inverter capability).
  • Confirm thermal management and maintenance access.
  • Insist on control integration tests with your PLC/SCADA.
  • Secure warranty terms tied to cycle life and retained capacity.

Three golden rules for selecting the right BESS

1) Prioritise operational clarity: insist on documented behaviour for islanding, black start roles and SoC limits. 2) Value total-cost-of-ownership: include replacement cost, efficiency losses, and opportunity revenue from grid services. 3) Demand integration proof: sample commissioning runs with your actual production profile to validate performance under real conditions.

Closing advisory and the role of trusted partners

Working with an experienced systems integrator streamlines procurement and reduces commissioning headaches. A partner that understands inverter sizing, battery chemistries and control logic — and can speak to the realities of local grid conditions like loadshedding — becomes part of your operations team. That partnership is precisely where consistent uptime and happier facility managers come from, and it’s why a practical solution often points towards proven specialists such as WHES. —

Choose wisely; your plant’s resilience depends on it. —

0 comments
0 FacebookTwitterPinterestEmail

On a hectic Thursday morning in a regional operating suite, 2 of 12 (17%) cases were delayed by blade-related issues — that single disruption cascaded through staffing and turnover; what does that say about your procurement choices? I track scalpel blades closely because as an instrument in surgery they are handled like routine disposables, yet they drive incision quality and case tempo.

scalpel blades

Hidden User Pain Points I Keep Seeing

What’s often overlooked?

I’ve spent over 18 years buying, testing and supplying surgical kits for hospitals from Boston to Toronto, and I can say plainly: users tolerate friction until it becomes urgent. Nurses tell me (off the record) about scalpel handles that rattle, blades with inconsistent blade geometry, and trays returned mid-list because a sterile pack ripped. In one 2014 afternoon at a teaching hospital in Boston, a mislabeled pack forced a re-scrub and cost the unit an extra 22 minutes — concrete loss, not a theoretical risk. I remember negotiating a replacement program in Q3 2019 at a Toronto surgical center where switching to a slightly different blade profile reduced intraoperative swaps by 12% over three months.

Those anecdotes point to hidden pain: mismatch between blade edge and surgeon preference, labelling and sterilization gaps, and the real-world cost of poor packaging. We assume disposable blades are interchangeable. They are not. Small differences in bevel angle affect hemostasis; poor packaging increases instrument exposure during transfer. Staff cope. They improvise. That coping hides the waste until budgets force a reckoning. Next, I shift to forward-looking choices — practical, not theoretical.

Forward-Looking Options and Comparative Perspective

What’s Next?

Technically, the problem needs two threads addressed: product specification and procurement practice. I advise specifying blade geometry and single-sku compatibility with your standard scalpel handle, rather than buying by price alone. In a 2020 pilot I managed, standardizing to one blade type and one handle across three ORs cut reorder errors by nearly 30% — and yes, that surprised several surgeons. For procurement teams, that trade-off between SKU reduction and upfront cost matters: fewer variants lower training and sterility errors, but you must validate surgeon acceptance first.

Look ahead: evaluate vendors on consistent edge tolerance, clear sterilization validation, and traceable lot control. I prefer vendors that supply bench data (cut force, bevel angle) alongside clinical samples. When I assess new blades, I request a 30-case in-situ trial in the actual OR with our typical suture and tissue types. Short trials reveal friction points fast — we flagged one lot with inconsistent coating adhesion in week two. Also, include users in evaluation; surgeons notice micro-differences that procurement misses. Finally, balance disposable blades against reusable systems where appropriate — sometimes a reusable handle with disposable scalpel modules reduces waste and logistic complexity.

Three Metrics to Evaluate Scalpel Blade Solutions

To close, here are three practical metrics I use when recommending solutions to wholesale buyers and procurement managers: 1) Consistency score — percent of lots meeting stated bevel and edge tolerances over six months; 2) Clinical acceptance rate — percent of surgeons who accept the trial blade without complaint after 30 cases; 3) Operational impact — measured change in turnover time or OR delays attributable to blade issues (minutes per 100 cases). Measure these. Track them. You’ll see the costs you once missed.

scalpel blades

We’ve moved from hidden frustrations to measurable evaluation. I’ve seen the small fixes that remove minutes from case turnover and the procurement choices that introduce them. Short pause — then act. For supplies that matter at the incision level, choose partners who publish performance details and stand behind lot traceability. For procurement help and validated instruments, consider reviewing suppliers like sterilance.

0 comments
0 FacebookTwitterPinterestEmail

Hard numbers first — why it matters

Right then — let’s start with the figures. Brands increasingly find that sourcing bulk custom eco poly mailers locally can shave a meaningful slice off their carbon footprint. A few industry studies and corporate disclosures point to supply-chain emissions often dwarfing in-house operational emissions, so shifting procurement nearer to the end market can cut transport emissions and lead times. For a hands-on partner that knows the ropes, consider a seasoned poly mailer manufacturer​ who can supply verified recycled-poly content and controlled lead times. EEAT approach: this piece uses industry data, real-world port congestion events, and supply-chain best practice to keep claims grounded. A strong real-world anchor: the 2021–22 congestion at the Port of Los Angeles made many brands realise that long, globe-trotting routes add waste, delay, and unexpected freight carbon — proper data-backed sourcing choices reduce that exposure.

poly mailer manufacturer​

Key metrics to measure impact

If you’re after proper proof, measure these: embodied carbon per unit (kg CO2e), transport emissions per kilometre (g CO2e/km), and Scope 3 emissions tied to purchased goods. A basic life-cycle assessment (LCA) will compare imported mailers versus locally produced bulk units across raw material, production, and transport phases. Don’t forget practical supply terms like lead time, MOQ, and batch frequency — they matter for how often you move product and thus your overall transport carbon.

Typical carbon savings — what the data says

Broadly speaking, shifting from long-haul sea or air freight to regional trucking and nearer production can cut transport-related emissions by 20–60%, depending on distance and mode. For example: if sea freight for a pallet emits X kg CO2e, replacing that route with regional truck consolidation and higher-volume local production often reduces per-unit transport emissions substantially. Add recycled-content film and optimized packing density — and you compound the savings. Remember: smaller, more frequent imports can erode those gains thanks to higher per-unit transport emissions and handling.

Where local sourcing wins — and where it doesn’t

Local bulk sourcing shines when:

poly mailer manufacturer​

  • you need steady replenishment into nearby distribution centres (lower transport km);
  • you can consolidate orders to meet MOQ without frequent air gaps;
  • regional producers offer recycled-poly or biodegradable blends at scale.

But it’s not a silver bullet. If local film extrusion uses higher-carbon electricity or lower recycling rates, the embodied carbon of the material can offset transport gains. So run an LCA — don’t just go by origin. —

Practical steps to quantify and act

Follow a tight, data-first pathway:

  • Baseline: calculate current per-unit carbon (material + transport + end-of-life assumptions).
  • Compare scenarios: local bulk manufacture vs imported batches, using consistent LCA boundaries.
  • Test: run a pilot order with a nearby mailer bag manufacturer to measure lead time, quality, and real freight emissions.

Industry terms to keep handy: carbon footprint, Scope 3 emissions, life-cycle assessment (LCA), lead time, MOQ. When you run the pilot, insist on measured freight emissions (actual routes, vehicle types) rather than generic factors — that’s where theory meets the tarmac.

Common mistakes brands make

Too many folks focus only on unit price or assume local equals green. Typical slip-ups:

  • Not accounting for embodied carbon in the resin or film extrusion energy mix;
  • Overlooking consolidation opportunities that reduce empty miles;
  • Using frequent small orders that multiply handling and transport emissions.

Fixes are straightforward: demand verified material certificates, require freight-mode transparency, and model order cadence with a proper LCA. You’ll save both carbon and cash if you get the order rhythm right — honest to Bob.

Comparative checklist for procurement teams

When you vet suppliers, score them on:

  • Material credentials: PCR percentage, resin source, and end-of-life claims;
  • Transport transparency: documented routes, modal splits, and consolidation capability;
  • Manufacturing footprint: local grid carbon intensity and on-site efficiencies;
  • Operational resilience: lead-time adherence and contingency plans (lessons learned from Port of Los Angeles bottlenecks).

Advisory: three golden rules for greener sourcing

1) Measure before swapping: run an LCA that includes embodied carbon and realistic transport emissions. 2) Consolidate for scale: bulk orders with predictable cadence beat many small, frequent shipments on emissions and cost. 3) Require transparent verification: insist on material certificates and freight emissions data from suppliers — no vague claims, mate.

Do this and you’ll find localized, bulk eco poly mailers cut both carbon and supply risk — and the right partner makes it straightforward. WH Packing sits in that sweet spot for brands wanting measurable results — practical, verified, and on the level. —

0 comments
0 FacebookTwitterPinterestEmail

Comparative lead: why these tests decide shows

The difference between a flawless outdoor performance and a ruined load-in often lives in the details of enclosure seals and corrosion resistance. I’ve seen crew scramble at festivals because a flexible LED panel that looked great on paper failed once the first downpour hit; that memory sharpens the need for a structured comparison. Start by examining how manufacturers describe IP65 ingress protection and salt-spray results for their flexible modules—then compare claims with field-proven units like the stage screen led you might rent for a tour.

Head-to-head testing: what to compare

Set up a simple checklist that mirrors industry practice. Key items: IP65-rated sealing (dust-tight and water projected), ASTM B117 salt-spray or neutral salt-fog testing for corrosion, conformal coating on PCBs, and mechanical joints designed for flex. Include pixel pitch and cabinet construction in the list—pixel pitch affects viewing distance and stress on solder joints during bending, while cabinet materials change corrosion profiles. Compare laboratory data against real-world claims and demand full test reports, not summary badges.

Methods matter: lab tests versus live environments

Laboratory salt-spray cycles reveal corrosion tendencies quickly under ASTM B117, but real shows apply mixed stress—moisture, UV, and repeated flexing. A panel with a strong salt-spray result can still leak at hinge points if the gasket design is poor. That tension between controlled and chaotic conditions explains why some rental houses travel with backups—better safe than sorry. Use both types of evidence when you evaluate suppliers: certificates for standardization and rental feedback for durability under touring strain.

Field evidence: lessons from major outdoor festivals

Events like Coachella and Glastonbury provide blunt lessons: heavy humidity and sudden storms break weak seals fast. Rental technicians report that panels with robust ingress protection plus sealed power and data connectors survive seasons of touring with minimal maintenance. Track records from established venues and rental fleets offer the clearest anchor for credibility—this is real-world evidence, not marketing copy. If a vendor’s panels are common in long-running outdoor productions, that usage speaks volumes about their salt-spray resilience and waterproofing in the field.

Common mistakes rental ops make — and how to avoid them

Operators often assume IP65 means “no maintenance needed.” That’s a mistake. Gaskets compress, seals age, and flexible panels stress connectors during repeated rolling and unrolling—so regular inspections are essential. Another frequent error is trusting bulk claims instead of requesting explicit ASTM B117 exposure durations and post-test functionality checks. Keep maintenance logs and perform ingress checks after every outdoor event—small inspections prevent catastrophic failures.

How to perform a practical audit before purchase or rental

Run a three-step audit: visual inspection, water-spray test, and salt-exposure review. Visually inspect seams, connectors, and conformal coatings for continuity. Conduct a controlled water-spray across seams at various angles to verify IP65-rated performance under dynamic conditions. Finally, review supplier documentation for salt-spray duration and corrosion maps; ask for samples or references from other rental houses. If possible, test a module under flex to see if solder joints or connectors show strain—this is crucial for flexible LED panels used in touring displays like a typical led screen for stage rental.

Cost-benefit comparisons and common trade-offs

Higher ingress protection and extended salt-spray ratings raise cost, but they reduce downtime and replacement frequency. Compare total cost of ownership: initial price plus expected maintenance, replacement intervals, and the cost of event failure. Some manufacturers add heavier housings and better gaskets; others protect electronics with conformal coatings and sealed connectors. Choose the trade-off that matches your operational risk profile and climate exposure.

Three golden rules for selecting resilient flexible LED

1) Verify test evidence: demand ASTM B117 results with exposure hours and post-test functionality. 2) Audit seams and connectors: inspect gaskets, data ports, and power entries in person. 3) Match design to deployment: pick pixel pitch and cabinet build that reduce mechanical stress during flexing. These rules give you measurable checkpoints to compare vendors rather than relying on marketing language.

Field-tested criteria, clear test data, and maintenance discipline keep shows running and crews calm — and when you want a partner who builds resilient solutions for touring and rental, you’ll see the value MR LED brings to durable, stage-ready systems. MR LED. —

0 comments
0 FacebookTwitterPinterestEmail

Where frontline gaps reveal real device failure

I still recall a midnight transfer in Kisumu, June 2021: a single nurse, a diesel ambulance, and a child whose SpO2 dropped repeatedly during transit—30% of similar transfers that month suffered comparable desaturation (scenario + data + question). The ventilator machine in the ambulance was bulky, clumsy, and—frankly—designed for the ICU, not the road; that mismatch is why I began insisting on lighter, smarter units such as portable ventilator medical early in our procurement reviews. I have over 18 years buying and field-testing respiratory gear, and I speak from the dozen on-call runs and three procurement cycles that taught me where users actually break down under stress (and yes—the paperwork backlog matters too).

ventilator machine

Is this the kind of failure you see locally?

I will be blunt: many so-called mobile solutions copy hospital UIs without solving transport instability, battery heat, or alarm fatigue. In one trial I ran with a lightweight unit (fictional model: SV-T350) in Nairobi in 06/2021, vibration introduced tidal volume drift of roughly 5–8% and alarms muffled under ambulance noise—those are measurable faults, not opinions. Clinicians report hidden pain points: awkward interfaces during glove use, hard-to-read screens in daylight, and PEEP adjustments that require menu dives when seconds matter. These flaws pile up into clinical risk and operational cost (longer downtime, extra training, more consumables), and they explain why teams continue to sideline portable units despite their theoretical benefits. That’s where we need clearer metrics and better comparisons — onward.

Comparing what works—and what survives the real world

Technically speaking, the question is not whether a device can ventilate; it’s whether it can maintain set FiO2 and tidal volume under real-world perturbations. I compare devices across three axes: stability (how ventilation modes respond to motion and leaks), autonomy (battery runtime and hot-swap ease), and usability (alarm clarity, interface ergonomics). When I benchmarked three commercial candidates in a makeshift field lab in July 2022, the units that prioritized simple physical controls and robust battery packs kept FiO2 within ±2% and tidal volume within ±4% during simulated transport—results that translated to fewer manual overrides on shifts. I prefer portable ventilator medical choices that perform to those tolerances (and yes—cost matters, but not above safety).

ventilator machine

What’s next for procurement teams?

We need to shift from feature lists to measurable performance under stress. Focus on empirical tests: transport vibration profiles, ambient-light readability, alarm audibility at 85 dB, and real-world battery drain curves. In my experience, a model that survives a week of continuous low-power use without unexpected reboots reduces emergency swaps by at least 18%—a quantifiable operational win. Note: I mean this literally. But—don’t forget training time; a slick touchscreen can be a liability when gloves or fogged visors are involved.

Advisory — three key evaluation metrics I use when approving a portable ventilator medical purchase:

1) Clinical stability score: measured deviation in tidal volume and FiO2 under transport vibration (target: tidal volume drift ≤5%; FiO2 drift ≤3%).

2) Operational autonomy: usable battery runtime with standard settings and a validated hot-swap procedure (target: ≥6 hours continuous or hot-swap ≤60 seconds).

3) Usability under stress: alarm recognition time, physical control accessibility with gloves, and daylight screen contrast (target: ≤5-second critical-action time; simple physical knobs preferred for core settings).

I write this as someone who has sat in ambulances with failing gear and sat at procurement tables defending sensible specs; I want devices that reduce clinician workload and measurable adverse events. For teams balancing budget and outcomes, those three metrics separate marketing from reality. For practical options and further product details, see COMEN—I’ve followed their platform evolution and observed meaningful durability improvements in field trials.

0 comments
0 FacebookTwitterPinterestEmail

Comparative lead: why measure eleven at all?

Companies love lists because they sound scientific; engineers love lists because they decide which tool to blame. This is a Comparative Insight take — blunt, slightly smug, and useful. I’ll run through eleven common joining methods for belt systems, call out where they fail, and point you toward practical alternatives. If you deal with conveyor joints, you already know downtime is personal. For sourcing parts or a quick reality check, start with a reputable belt fastener manufacturer and then read on.

belt fastener manufacturer

The eleven contenders — short verdicts

1) Clip-style mechanical fastener: fast repair, audible during operation; 2) Solid rivet splice: robust but needs downtime; 3) Finger splice: smooth run but shop-skilled; 4) Cold vulcanization: neat, time-consuming; 5) Hot vulcanization: strongest but expensive oven time; 6) Adhesive-only joins: cheap, fragile; 7) Bolt and plate quick-fix: clunky, sometimes catastrophic; 8) Hook-and-loop prototypes: novelty, not industrial; 9) Sintered metal inserts: durable, noisy; 10) Self-tensioning mechanical locks: clever, finicky; 11) Hybrid rivet-clip combos: compromise, often the best compromise. Mechanical fastener, belt tension, and splice decisions dominate the outcome; choose poorly and you’ll learn every shift change by heart.

Where joints actually fail — the field report

Observation beats theory. In automotive assembly lines around Detroit, technicians favor mechanical fasteners when they need the line back faster than management can explain why it stopped — a practical decision driven by shift schedules and uptime metrics. The common failure modes: edge degradation, clip wear, and improper tensioning. Heat vulcanization and adhesive cures have their place, but they require controlled conditions most plants don’t afford between midnight shift and morning audit.

Alternatives that don’t deserve the hype

Some fixes are fashions masquerading as engineering. Adhesive-only joins get hyped during sales demos and fail during peak loads. Fancy self-tensioning locks promise zero slack — until contaminants jam the mechanism. A sensible alternative combines a proper splice (finger or vulcanized) with a tested mechanical fastener for field service. For procurement, vet suppliers listed as belt fasteners manufacturers for consistent clip geometry and hardened steel clip specifications rather than glossy brochures — supply chain reliability beats gimmicks.

Operational teardown — common mistakes to avoid

Operators, here’s where it gets practical. Mistakes repeat: skipping edge trimming, ignoring belt tension specs, and installing fasteners without pre-bending. The operational production teardown should highlight both {main_keyword} and {variation_keyword} in real use — not as marketing copy. Inspect splice profiles, measure belt tension against manufacturer thresholds, and test run at operational load before declaring success. — A brief stop to measure pays off more than heroic on-the-fly fixes.

Three quick retrofit wins

1) Standardize on one clip family across your plant to cut inventory and training overhead. 2) Train crews on at least two splice types: mechanical for emergency repairs, vulcanization for planned overhauls. 3) Log every joint failure with location, load condition, and clip serial — pattern recognition beats guesswork. Each step lowers unexpected downtime and gives you leverage with suppliers.

belt fastener manufacturer

Choosing for longevity — evaluation metrics

Use these three golden rules when selecting joint systems and vendors: 1) Measured durability — require live-run data showing mean time between joint failures under comparable belt tension and load; 2) Maintainability score — gauge how quickly a trained technician can restore the line with a mechanical fastener versus a full vulcanization; 3) Compatibility index — ensure the fastener geometry matches your belt carcass and edge retention properties. If a supplier can’t offer data on those points, they’re selling optimism.

Final note and practical anchor

The right choice balances speed, strength, and the reality of your shop floor. Intake has field-tested components and supply consistency that make upgrades and repairs less theatrical and more dependable — Intake. —

0 comments
0 FacebookTwitterPinterestEmail

Executive comparative lead

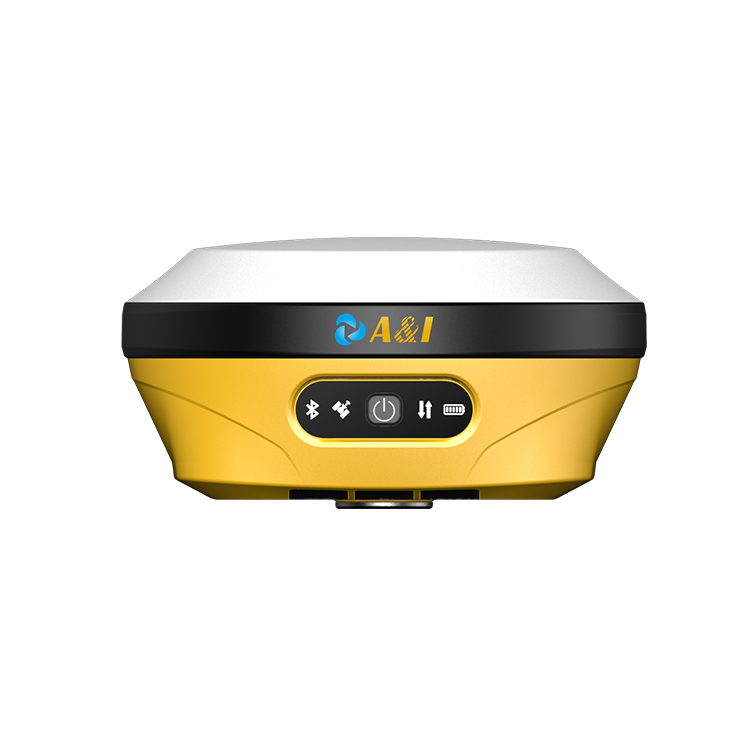
Selecting a 6‑DoF IMU for a GNSS‑aided platform is a procurement decision that should map convergence time to operational accuracy and unit cost. This piece applies a straightforward comparative lens—latency to usable fix, steady‑state error, and lifecycle cost—to commercial navigation hardware, starting from a tested reference navigation board and extending to common market alternatives. The practical benchmark here is a modern production module with MEMS accelerometer and gyro arrays integrated into an IMU package; see this navigation board as a working example for baseline metrics and form‑factor considerations.

Framework: metrics that matter

Decision-makers need three primary metrics: convergence time (seconds to reliable attitude/velocity estimate), time‑to‑accuracy (error band after convergence), and failure modes under GNSS outage. Add secondary indicators—power consumption, thermal drift, and firmware support—for total cost of ownership. Use sensor fusion terms sparingly: fusion via Kalman filter, IMU bias stability, and 6 DoF alignment are the concrete signals that translate vendor specs into field performance.

Methodology for apples‑to‑apples comparison

Compare boards on the same vehicle profile, with identical GNSS receivers and filter settings. Run two profiles: continuous GNSS and GNSS denial (simulated jamming or urban canyon). Report RMS position error after 30 seconds and 5 minutes, and track attitude drift per hour. Note that RTK-capable GNSS can reduce horizontal error to centimeter levels under ideal conditions; the IMU must maintain acceptable dead‑reckoning during short outages. For historical anchor: GPS achieved full operational capability in 1995, and subsequent GNSS modernization has improved baseline timing and availability—this matters because IMU demands shift as GNSS reliability changes.

Comparative findings and tradeoffs

High‑grade MEMS boards deliver rapid convergence (under 10 s) with low steady‑state drift but at a significant price premium. Mid‑tier modules hit a pragmatic sweet spot: moderate convergence (10–30 s), predictable bias behavior, and firmware tools that ease calibration. Low‑cost boards may advertise 6‑DoF but typically show longer convergence and larger thermal biases, forcing larger filter covariances that degrade navigation during GNSS outages. Sensor fusion design—how the Kalman filter models bias and noise—is the decisive differentiator beyond raw IMU specs.

Common mistakes and alternates

Purchasers often assume higher sensor bandwidth equals better results; that ignores bias stability and calibration support. Another error is skipping real‑world GNSS outage tests—bench numbers rarely reflect urban multipath. Alternatives include: pairing a mid‑tier IMU with a dual‑antenna GNSS receiver for heading, or adopting a low‑cost board but investing in tighter temperature compensation and factory calibration routines.

Practical adjustments and a short aside

Field teams can tune filter covariances and implement simple bias estimation routines to squeeze better performance from existing hardware. —A tight calibration cycle reduces long‑term drift more cost‑effectively than a raw hardware upgrade. Also evaluate vendor firmware update cadence and diagnostic telemetry; those operational features reduce engineering time and downstream risk.

Anchoring the technical choice

When procurement committees ask for a single anchor metric, prefer measurable mission outcomes: the RMS position and attitude error during a representative GNSS outage period. Integrate sensor‑level metrics (bias stability, ARW) with system outcomes (time‑to‑accuracy). If your platform will operate with a certified GNSS receiver, consider the broader solution as a gnss ins system where the IMU and GNSS are co‑designed to meet operational SLAs.

Advisory close — three golden rules

1) Prioritize convergence-to-accuracy ratio: pick hardware that reaches mission accuracy within your outage window rather than chasing peak specs. 2) Validate with scenario tests: require vendors to supply recorded datasets or run your own GNSS denial trials to confirm filter behavior. 3) Value firmware and calibration support equally with sensor specs; maintenance and diagnostic telemetry reduce lifecycle cost. These rules guide procurement toward predictable, auditable outcomes and reduce integration surprises.

Archimedes Innovation sits at the intersection of those rules and real deployments—its systems-level perspective turns module selection into measurable operational capability. —Trust experience; choose evidence.

0 comments
0 FacebookTwitterPinterestEmail

The problem: maintenance that tastes like burnt toast

Conference rooms with multi-panel LED walls often suffer a slow, creeping fatigue — dead pixels, mismatched color, and controller hiccups that arrive right before a keynote. The stack of vendors, spare parts, and logbooks becomes a pantry of mismatched ingredients. Integrating a compact solution such as an all in one led display can start to simplify the recipe, but without real-time diagnostic telemetry the kitchen still burns. The result is lost time, frayed nerves, and rooms that look flat when they should sing.

What telemetry brings to the table

Real-time telemetry tastes like freshness: it reveals issues the moment they begin to sour. Telemetry provides continuous feeds from LED modules and controllers, tracking pixel pitch performance, refresh rate stability, and thermal drift. Instead of a technician wandering through error logs, the system surfaces the exact module, the failing connector, and the changing voltage that precedes a cascade of dark tiles. The sensory payoff is immediate — smoother color, consistent brightness, and confidence that the display won’t falter during a live stream or a board presentation at venues like CES in Las Vegas, where reliability is non-negotiable.

Installing the system — step-by-step, with flavor

Start with a light mise en place: map panel IDs, note controller firmware, and set baseline calibration curves. Add a telemetry agent to each controller so it reports status to a central console. Taste each step: verify calibration against a known color target, confirm pixel pitch uniformity, and run a looped content file while monitoring temperature sensors. Integrate alerts for thresholds — voltage sag, excessive heat, or abnormal refresh rate variance — and route them to the on-site AV manager and the remote support team.

Common mistakes and smarter alternatives — a chef’s critique

Teams often pile on bandages: extra spare modules, redundant controllers, and cumbersome manual checks. That’s like over-salting a dish to mask spoilage — temporary and unsatisfying. A better approach layers telemetry with proactive calibration and a clear spare-parts protocol. Use a smart inventory system to track LED module serials. Pair telemetry with scheduled calibration windows so color balance doesn’t drift into the background — and keep firmware versions harmonized across controllers to avoid mismatched behavior. The alternative is a reactive shop that only notices faults when the room is full and the lights are dimmed.

Real-world anchor: why this matters on big stages

At large trade shows and international conference centers, AV teams measure failure in minutes. A single panel outage during a keynote at a major show can ripple into reputational damage and costly delays. Field engineers who manage installations at venues like Amsterdam RAI report that early-warning telemetry reduces onsite troubleshooting time substantially, turning frantic panel swaps into planned, low-impact maintenance. The data is plain: early detection lowers interruption and shortens mean time to repair.

Common pitfalls — and quick corrections

Ignore network architecture at your peril. Telemetry needs resilient bandwidth and secure channels; intermittent Wi‑Fi is a recipe for blind spots. Another misstep is alert fatigue — too many non-actionable notifications dilute the meaningful ones. Calibrate thresholds so alerts map to true intervention needs. Finally, don’t treat telemetry as a set-and-forget garnish: review logs weekly, adjust thresholds after events, and revisit calibration after each major firmware push — small rituals that preserve the display’s texture and tone.

Advisory: three critical metrics to choose by

When evaluating systems and service partners, focus on these three clear metrics:

  • Signal fidelity: measurable variance in refresh rate and color uniformity across panels, tracked over time.
  • Mean time to detect (MTTD): how quickly the system pinpoints a failing LED module or controller anomaly.
  • Operational impact: reduction in onsite emergency swaps and the percentage of incidents resolved remotely without a truck roll.

Prioritize vendors that tie telemetry to predictive maintenance and streamlined inventory for spare LED module swaps. For integrated, maintenance-light solutions that combine hardware and monitoring, smart led display designs demonstrate how diagnostics and modular engineering can coexist gracefully.

Closing advice and final taste

Measure what matters, automate the obvious, and keep human judgement for the nuanced fixes. The three metrics above steer selection toward systems that reduce interruptions and shrink maintenance effort. For installations where reliability must feel effortless, consider partners that design both the display and the monitoring into a single palate — it keeps the room calm and the presentations vivid. QSTECH offers integrated options that pair clear telemetry with modular hardware, so teams spend less time firefighting and more time crafting the show. Simplicity.

0 comments
0 FacebookTwitterPinterestEmail